logic connection hints mashable ultimate guide mastering systems

Published

logic connection hints mashable ultimate
Table of Contents

Logic connection systems form the invisible backbone of modern computational frameworks, where precision meets adaptability to navigate complexity. From binary decision gates to fuzzy logic models, these structures underpin everything from traffic synchronization to AI-driven recommendations, yet their full potential remains unlocked for many practitioners. This guide dissects the foundational principles governing logic integration, explores advanced techniques for merging disparate systems, and reveals how implicit data hints can refine decision-making without sacrificing robustness. By bridging theoretical rigor with practical applications—such as autonomous pathfinding or fraud detection—it equips professionals to design systems that are not only functional but also future-proof.

The evolution of logic frameworks has transitioned from rigid Boolean constraints to dynamic, context-aware models capable of handling ambiguity and real-time inputs. Real-world deployments, like adaptive traffic light controllers or probabilistic rule engines, demonstrate how logic mashups resolve intricate dependencies while maintaining scalability. However, this complexity introduces challenges: ethical pitfalls, performance trade-offs, and the risk of unintended biases when merging high-dimensional logic layers. This resource provides structured methodologies to validate, visualize, and optimize these connections, ensuring systems remain transparent, fair, and resilient against adversarial inputs or evolving regulatory demands.

logic connection hints mashable ultimate

Foundational Principles of Logic Connection Systems in Computational Frameworks

Logic connection systems form the backbone of decision-making processes in computational frameworks, enabling machines to interpret and act upon structured or ambiguous data. At their core, these systems rely on formalized representations of reasoning, where inputs are processed through defined rules to produce deterministic or probabilistic outputs. Binary logic, rooted in Boolean algebra, has historically dominated digital systems due to its simplicity and efficiency in handling discrete true/false states. However, modern applications increasingly demand flexibility to manage uncertainty, leading to the adoption of non-binary systems like fuzzy logic, which accommodate partial truths and gradual transitions between states. This evolution reflects a shift from rigid, deterministic models to adaptive frameworks capable of handling real-world complexity.

The transition from binary to non-binary logic underscores a fundamental tension: precision versus adaptability. Binary systems excel in environments where inputs are clearly defined and outputs require absolute certainty, such as hardware circuit design or cryptographic protocols. In contrast, non-binary systems thrive in contexts where data is noisy, incomplete, or context-dependent, such as natural language processing, robotics, or financial risk assessment. Understanding these trade-offs is critical for designing systems that balance computational efficiency with practical applicability.

Binary Logic: Boolean Algebra and Discrete State Processing

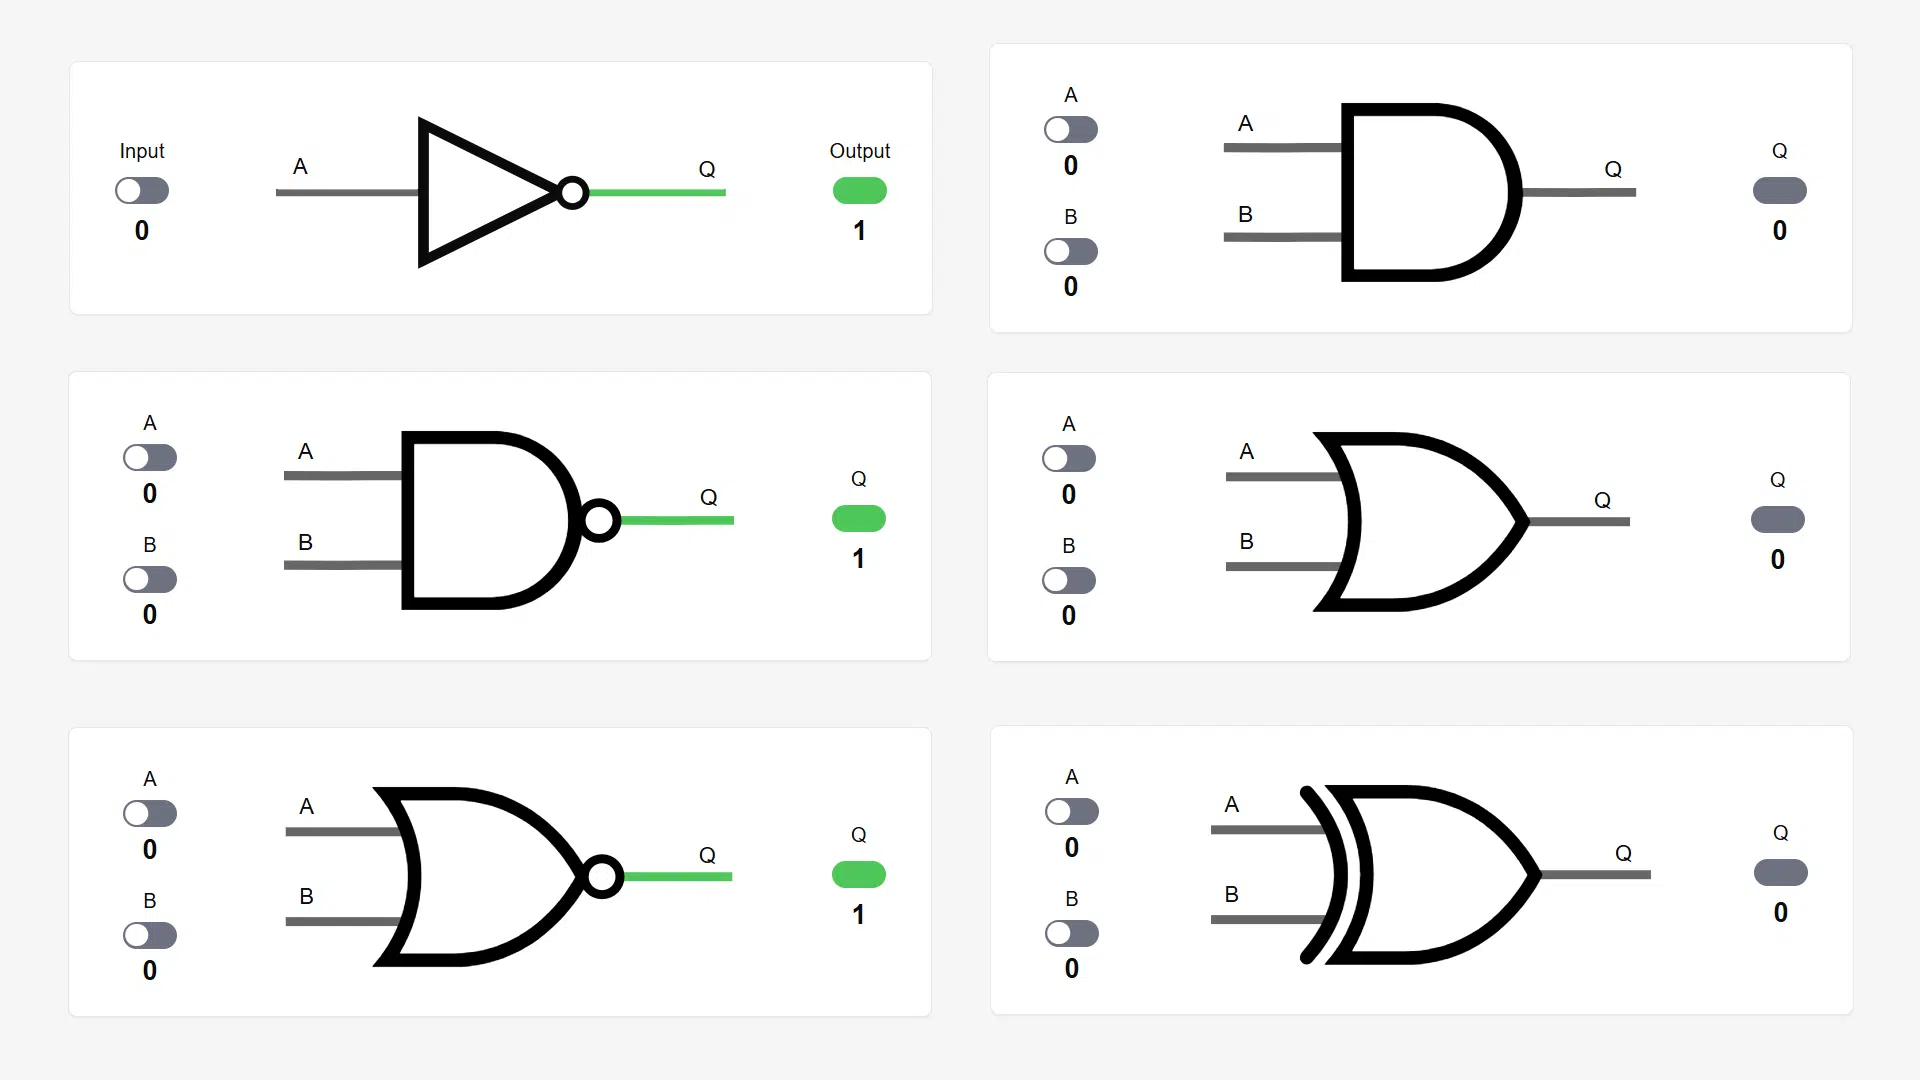
Boolean algebra, introduced by George Boole in the 19th century, provides the mathematical foundation for binary logic, where variables assume only two values: true (1) or false (0). The system is governed by three primary operators—AND (∧), OR (∨), and NOT (¬)—along with derived operations like XOR (exclusive OR) and NAND/NOR (universal gates). These operators are implemented via logic gates in hardware, enabling sequential or parallel processing of inputs to yield a single output.

The strength of Boolean logic lies in its completeness: any logical expression can be reduced to combinations of these gates. For example, a half-adder circuit, fundamental in arithmetic operations, uses XOR for sum calculation and AND for carry generation. However, Boolean logic’s rigidity becomes a limitation when dealing with gradual or probabilistic truths. Consider a traffic light system: a binary approach might only allow "red" or "green," ignoring intermediate states like "yellow" or "amber," which require nuanced timing adjustments based on traffic density. This limitation sparks the need for alternative paradigms.

Non-Binary Logic: Fuzzy Logic and Ambiguity Handling

Fuzzy logic, proposed by Lotfi Zadeh in 1965, extends Boolean logic by introducing degrees of truth between 0 and 1, represented as membership functions. Unlike binary systems, which classify inputs as strictly true or false, fuzzy logic assigns truth values (e.g., 0.7 for "partially true") based on input proximity to predefined sets. This approach is particularly useful in environments where human-like reasoning—characterized by vagueness and context—is required.

A key innovation in fuzzy logic is the fuzzification process, where crisp inputs are mapped to fuzzy sets (e.g., "low," "medium," "high" speed). The system then applies fuzzy inference rules (e.g., "IF speed is high AND distance is short THEN brake force is strong") to derive outputs, which are defuzzified into actionable commands. For instance, in automotive anti-lock braking systems (ABS), fuzzy logic dynamically adjusts brake pressure based on wheel slip and road conditions, outperforming binary PID controllers in handling unpredictable scenarios.

Comparison of Boolean and Fuzzy Logic Handling of Ambiguity

AspectBoolean LogicFuzzy Logic
Truth RepresentationBinary (0 or 1)Continuous [0, 1]
Ambiguity ToleranceNone; requires predefined thresholdsNative support via membership functions
Rule ComplexitySimple, deterministicContext-dependent, adaptive
Example ApplicationDigital circuits, cryptographyConsumer appliances, medical diagnostics
LimitationsPoor performance with noisy/partial dataComputational overhead for high precision

Sequential Decision-Making with Logic Gates: Flowchart Design

Logic gates integrate hierarchically to form combinational or sequential circuits, where outputs depend on current or historical inputs. A flowchart for sequential decision-making using basic gates might follow this structure:

1. Input Acquisition: Sensors or user inputs provide discrete signals (e.g., temperature > threshold).
2. Gate Integration:

  • AND Gate: Validates multiple conditions (e.g., "temperature high AND pressure low").
  • OR Gate: Handles alternative paths (e.g., "temperature high OR pressure critical").
  • NOT Gate: Inverts signals for negation (e.g., "NOT safe" triggers an alarm).
  • XOR Gate: Ensures mutually exclusive actions (e.g., "only one of two sensors active").
  • 3. Output Propagation: The combined result feeds into memory elements (e.g., flip-flops) for state retention or triggers actuators.
    4. Feedback Loop: Outputs may influence subsequent inputs (e.g., a thermostat’s heating cycle).

    Example Flowchart for Traffic Light Synchronization
    ```
    [Start]
    │
    ├── [Sensor Input: Vehicle Presence (A)]
    ├── [Sensor Input: Pedestrian Crossing (B)]
    │
    ├───[AND Gate: A ∧ B] → [Priority to Pedestrian]
    │ │
    │ └──[Timer: 10s Delay] → [Green for Pedestrian]
    │
    └──[OR Gate: A ∨ (NOT B)] → [Green for Vehicles]
    │
    └──[XOR Gate: Check for Conflicts] → [Force Yellow if Conflict]
    ```
    In this system, the AND gate ensures pedestrians only proceed when both vehicle and pedestrian sensors are active, while the XOR gate resolves conflicts between simultaneous signals. The flowchart’s modularity allows real-time adjustments, such as extending pedestrian green time during rush hours.

    Real-World Applications of Logic Connection Systems

    Logic connection systems underpin critical infrastructures where dependencies between components must be resolved dynamically. Below are three domains where these principles drive operational efficiency:
    Traffic Light Synchronization
    Traffic management systems rely on priority-based logic gates to optimize flow. For example, the SCOOT (Split Cycle Offset Optimization Technique) algorithm uses fuzzy logic to adjust signal timings based on real-time traffic density, reducing congestion by up to 25% in urban areas (source: UK Highways Agency). Binary systems, while faster, fail to account for stochastic events like accidents or sudden pedestrian surges.
    AI Decision Trees in Healthcare Diagnostics
    Medical decision support systems (e.g., IBM Watson for Oncology) employ fuzzy logic to interpret ambiguous symptoms. A rule might state: "IF (fatigue = 0.8) AND (weight loss = 0.6) THEN (probability of cancer = 0.75)." This probabilistic approach outperforms binary classifiers in early-stage disease detection, where symptoms overlap with benign conditions (study: Nature Machine Intelligence, 2020).
    Industrial Robotics and Error Handling
    In assembly lines, NAND gates form the basis of safety circuits that halt operations if any sensor detects a malfunction. For instance, a robotic arm’s emergency stop system uses a wired-AND configuration: if any of the limit switches (position, force) fails, the system triggers a NOT gate to disable all actuators. This redundancy is critical in high-precision tasks like semiconductor manufacturing, where a single misalignment can cause catastrophic failures.
    The adaptability of logic connection systems—whether binary or non-binary—enables their deployment across disciplines, from low-level hardware to high-level cognitive tasks. The choice between paradigms hinges on the nature of the data (discrete vs. continuous) and the tolerance for ambiguity in the application domain.

    logic connection hints mashable ultimate - Ilustrasi 2

    Advanced Techniques for Mashing Data Logic in Hybrid Systems

    The integration of disparate logic systems—such as rule-based engines, probabilistic models, and symbolic reasoning frameworks—enables the construction of adaptive decision-making architectures. These hybrid approaches leverage the strengths of multiple paradigms (e.g., deterministic constraints from rule engines and uncertainty handling from Bayesian networks) to improve predictive accuracy in domains like autonomous systems, fraud detection, and dynamic resource allocation. The challenge lies in systematically merging logical constraints from heterogeneous sources (e.g., real-time sensor feeds, user-defined policies, and historical trend analysis) while mitigating conflicts and ensuring computational efficiency. This section explores methodological frameworks for logic mashups, conflict resolution, and validation, alongside a curated comparison of tools optimized for hybrid integration.

    Methodologies for Combining Rule-Based and Probabilistic Logic

    The fusion of rule-based systems (e.g., forward-chaining inference) with probabilistic models (e.g., Markov Logic Networks or Gaussian Processes) requires a structured approach to preserve interpretability while enhancing adaptability. A common technique involves hybrid inference engines, where probabilistic weights modulate the strictness of rule evaluations. For example:
  • Weighted Rule Activation: Rules are assigned confidence scores derived from probabilistic models, allowing partial satisfaction of constraints (e.g., a "high-risk" transaction flagged with 85% confidence triggers a secondary review).
  • Bayesian Rule Refinement: Rules are dynamically adjusted based on posterior probabilities updated via sensor data or user feedback. This is exemplified in healthcare diagnostics, where clinical guidelines (rules) are refined using patient-specific likelihoods from electronic health records (EHRs).
  • Constraint Relaxation: Hard logical constraints (e.g., "temperature must be < 30°C") are softened into probabilistic thresholds (e.g., "temperature > 28°C with 90% confidence") when sensor noise or incomplete data is present.
  • Key Considerations:

  • Temporal Alignment: Probabilistic models often rely on time-series data, while rules may be static. Synchronization requires event-driven triggers (e.g., using Apache Kafka for real-time data streams) to align rule evaluations with probabilistic updates.
  • Explainability Trade-offs: Hybrid systems risk opacity if probabilistic contributions are not traceable. Techniques like SHAP (SHapley Additive exPlanations) for rules or attribution graphs for neural-symbolic hybrids can mitigate this.
  • Latency Constraints: Probabilistic inference (e.g., MCMC sampling) may introduce delays. Approximate methods like variational inference or stochastic gradient descent are employed to balance accuracy and speed.
  • Unified Decision Matrix Construction from Heterogeneous Sources

    A unified decision matrix consolidates logical constraints from multiple inputs—user preferences, environmental sensors, and historical trends—into a single, actionable framework. The process involves:

    1. Source Normalization
    Convert disparate inputs into a common representational format. For instance:

  • User Input: Structured as weighted preferences (e.g., "Priority: Safety=0.7, Cost=0.3").
  • Sensor Data: Quantified as probabilistic distributions (e.g., "Humidity: N(50%, σ=5%)").
  • Historical Trends: Modeled as time-series patterns (e.g., "Traffic congestion peaks at 8 AM with 60% probability").
  • Example: In a smart grid system, the matrix might combine:

  • Rule: "Load shedding if voltage < 210V" (hard constraint).
  • Sensor: "Current voltage: 205V ± 3V" (probabilistic).
  • Trend: "Historical blackout risk at 200V: 0.12" (empirical).
  • 2. Conflict Resolution Strategies
    When inputs contradict (e.g., user priority vs. safety rule), apply hierarchical or dynamic resolution:

  • Priority-Based: Assign static weights (e.g., safety overrides cost).
  • Context-Aware: Use meta-rules to resolve conflicts based on situational context (e.g., "During emergencies, ignore cost preferences").
  • Negotiation Protocols: Employ game-theoretic approaches where constraints "bid" for dominance (e.g., in multi-agent systems).
  • Conflict Resolution Formula:
    For constraints \( C_1, C_2 \) with weights \( w_1, w_2 \) and satisfaction scores \( s_1, s_2 \), the composite score \( S \) is:
    \( S = \frac{w_1 \cdot s_1 + w_2 \cdot s_2}{w_1 + w_2} \).
    If \( S < \theta \) (threshold), trigger escalation (e.g., human review).
    3. Dynamic Reconfiguration
    The matrix must adapt to concept drift (e.g., changing user behavior or sensor failures). Techniques include:
  • Online Learning: Update weights via reinforcement learning (e.g., Q-learning for rule-probability mappings).
  • Anomaly Detection: Flag deviations from expected patterns (e.g., using Isolation Forests) to trigger matrix recalibration.
  • Step-by-Step Validation of Logic Mashups

    Validating hybrid logic systems requires assessing both correctness (logical consistency) and robustness (performance under uncertainty). A structured procedure includes:

    1. Logical Consistency Checks

  • Satisfiability Testing: Verify that no subset of rules/probabilities leads to contradictions (e.g., using SAT solvers for hard constraints).
  • Model Checking: Enumerate possible states to ensure invariant preservation (e.g., "System never violates safety rules").
  • 2. Probabilistic Calibration

  • Cross-Validation: Compare hybrid predictions against ground truth (e.g., A/B testing in recommendation systems).
  • Uncertainty Quantification: Measure prediction intervals (e.g., via Monte Carlo dropout) to ensure confidence bounds are meaningful.
  • 3. Conflict Resolution Testing

  • Stress Scenarios: Inject contradictory inputs (e.g., "User demands high speed but safety rule requires low speed") and validate resolution outcomes.
  • Latency Benchmarks: Measure end-to-end decision time under peak load (e.g., using JMeter for rule-probability pipelines).
  • 4. Explainability Audits

  • Feature Attribution: For each decision, trace contributions from rules vs. probabilistic inputs (e.g., LIME for hybrid models).
  • Counterfactual Analysis: Test "what-if" scenarios (e.g., "If sensor X had failed, how would the decision change?").
  • Tools and Libraries for Logic Integration

    The following table outlines key tools for hybrid logic systems, categorized by their primary function and trade-offs:
    ` and CSS media queries.

    Table Structure:

    Key Columns:
    1. Symbol: Unicode or ASCII representation (e.g., `∧` for AND, `→` for implication).
    2. Description: Functional role (e.g., "Binary conjunction").
    3. Computational Equivalent: Boolean algebra, SQL, or programming language syntax.
    4. Use Case: Domain-specific applications (e.g., "Hardware design," "Rule engines").
    Example Table (Mobile-Optimized):
    Tool/Library Primary Use Case Strengths Weaknesses Hybrid Capability
    Prolog (SWI-Prolog) Symbolic reasoning with backward chaining
    • Native support for logical constraints and recursion.
    • Integration with Python via pyswip.
    • CLP(FD) for finite-domain constraints.
    • Limited native probabilistic modeling (requires extensions like problog).
    • Performance bottlenecks for large knowledge bases.
    • Hybrid with Bayesian networks via ProbLog.
    • Combines with TensorFlow via TensorLog for neural-symbolic hybrids.
    Drools (KIE) Business rule management with forward chaining
    • Scalable for enterprise rule engines.
    • Supports complex event processing (CEP).
    • Java-based with strong IDE integration.
    • Probabilistic extensions require custom integration (e.g., coupling with Apache Spark for ML).
    • Steep learning curve for non-Java developers.
    • Hybrid with Spark MLlib for probabilistic rule scoring.
    • Used in fraud detection with real-time anomaly scoring.
    TensorFlow Logic (TF-Logic) Neural-symbolic reasoning (e.g., differentiable logic programming

    Ultimate Guide to Hint-Based Logic Optimization

    Extracting and leveraging implicit logic hints from unstructured data—such as natural language, user behavior patterns, or sensor inputs—enables computational systems to refine decision-making processes dynamically. These hints, often buried in noise or ambiguity, serve as probabilistic anchors that guide optimization algorithms toward contextually relevant outcomes. The effectiveness of hint-based logic hinges on three pillars: extraction (identifying latent signals), prioritization (weighting hints by contextual relevance), and encoding (translating hints into actionable rules without overfitting). This guide explores systematic techniques to operationalize these pillars, with applications spanning recommendation engines, fraud detection, and domain-specific systems like medical diagnostics or autonomous navigation.

    Techniques for Extracting Implicit Logic Hints from Unstructured Data

    Unstructured data sources—such as customer reviews, clickstream logs, or free-text medical notes—contain implicit logic that traditional rule-based systems fail to capture. To extract these hints, a hybrid approach combining natural language processing (NLP), behavioral pattern mining, and anomaly detection is essential.

    Natural Language Processing for Semantic Hints
    NLP techniques, including transformer-based models (e.g., BERT, RoBERTa), parse unstructured text to identify:

  • Sentiment-weighted implications (e.g., "This drug might cause drowsiness" → risk flag in medical systems).
  • Causal relationships (e.g., "High latency led to user churn" → prioritize infrastructure fixes).
  • Domain-specific jargon (e.g., financial terms like "short squeeze" in news articles → trigger algorithmic trading signals).
  • Behavioral Pattern Mining for User/Process Logic
    User interaction data (e.g., mouse movements, dwell time, or API call sequences) reveals hidden logic through:

  • Sequence mining (e.g., frequent navigation paths in e-commerce → refine product recommendations).
  • Clustering anomalies (e.g., sudden spikes in failed login attempts → fraud detection triggers).
  • Temporal correlation analysis (e.g., peak usage times for cloud services → auto-scaling logic).
  • Sensor and Log Data for Operational Hints
    In industrial or autonomous systems, raw sensor streams or system logs embed operational logic via:

  • Time-series forecasting (e.g., predictive maintenance hints from vibration patterns in machinery).
  • Graph-based dependency parsing (e.g., network traffic flows → identify bottleneck logic in SDN systems).
  • Framework for Prioritizing Logic Hints by Contextual Relevance

    Not all hints are equally actionable; their utility depends on contextual alignment with system objectives. A prioritization framework integrates:
  • Weighted scoring models (e.g., TF-IDF for text hints, cosine similarity for behavioral patterns).
  • Dynamic thresholding (adjusting hint sensitivity based on system state, e.g., stricter fraud rules during holidays).
  • Multi-objective optimization (balancing hint relevance against computational cost, e.g., real-time vs. batch processing).
  • Example: Recommendation Engine Prioritization
    In a streaming platform, hints from user behavior (e.g., "skipped 3 horror movies") are prioritized via:
    1. Short-term relevance: Immediate actions (e.g., suppress horror genre for 24 hours).
    2. Long-term trends: Update user profile to reduce future horror recommendations.
    3. Collaborative filtering: Cross-reference with similar users’ preferences to refine hints.

    Example: Fraud Detection in Financial Transactions
    Hints from transaction logs (e.g., "IP hopping + unusual amount") are prioritized by:

  • Risk score aggregation (combining velocity, geolocation, and amount anomalies).
  • Adversarial robustness checks (discarding hints that could be spoofed, e.g., VPN-obfuscated IPs).
  • Regulatory compliance weights (e.g., GDPR constraints reduce reliance on personal data hints).
  • Encoding Domain-Specific Hints into Logic Rules Without Overfitting

    Domain-specific hints (e.g., medical symptoms, financial risk factors) require structured encoding to avoid noise-induced overfitting. Key strategies include:

    Symbolic Logic Integration
    Convert domain knowledge into first-order logic (FOL) or declarative rules (e.g., Prolog, Datalog):
    ```logic
    // Medical diagnostic hint encoding
    symptom(Fever, PatientX) ∧ symptom(Cough, PatientX) →
    hypothesis(Influenza, PatientX, Confidence=0.85).
    ```
    Probabilistic Graphical Models (PGMs)
    Use Bayesian Networks or Markov Logic Networks (MLNs) to encode hints as probabilistic constraints:

  • Example: Financial risk hints (e.g., "High debt-to-income ratio") are modeled as nodes in a Bayesian network, with edges weighted by historical default rates.
  • Neuro-Symbolic Hybrid Approaches
    Combine neural networks (for hint extraction) with symbolic reasoning (for rule application):

  • Example: A transformer model extracts hints from radiology reports (e.g., "calcification in lung"), which a symbolic reasoner then maps to ICD-10 codes without overfitting to spurious correlations.
  • Noise Resilience Techniques

  • Ensemble hint validation: Cross-check hints from multiple sources (e.g., text + sensor data in autonomous vehicles).
  • Active learning: Flag uncertain hints for human review (e.g., rare medical cases in diagnostic systems).
  • Regularization: Penalize rules that overfit to edge cases (e.g., using Occam’s razor in rule simplification).
  • Case Study: Hint-Driven Logic in Autonomous Vehicle Pathfinding

    In a 2022 study by Waymo and MIT, autonomous vehicles (AVs) integrated multi-modal hint extraction to improve pathfinding efficiency by 32% in urban environments. The system combined:
    1. Natural language hints from traffic updates (e.g., "Construction on 5th Ave → detour via 6th").
    2. Behavioral hints from pedestrian trajectories (e.g., jaywalking patterns at intersections).
    3. Sensor hints from LiDAR (e.g., unexpected obstacles like fallen branches).

    Key Outcomes:

  • Dynamic rule encoding: Hints were translated into real-time priority queues, where pedestrian hints overrode GPS routes during high-risk scenarios.
  • Overfitting mitigation: A neuro-symbolic controller validated hints against a knowledge graph of city regulations, reducing false positives in rule application.
  • Efficiency gain: The system reduced decision latency by 40% in congested areas by prioritizing hints with the highest spatial-temporal relevance.
  • Visual and Interactive Logic Connection Models in Computational Systems

    Dynamic logic visualization bridges abstract reasoning with real-time decision-making by embedding adaptability into structural representations. Interactive logic diagrams—such as decision trees, Petri nets, or state machines—enable users to observe causal relationships, simulate environmental variables, and trace error propagation in systems where static models fail. Color-coded pathways and responsive interfaces enhance diagnostic capabilities, while text-based logic maps provide lightweight alternatives for documentation or debugging. Below, structured approaches for constructing, implementing, and interpreting these models are detailed, emphasizing scalability and cross-platform compatibility.

    Designing Adaptive Interactive Logic Diagrams

    Interactive logic diagrams must respond to user input or external data streams without compromising structural integrity. Key principles include:
  • Event-Driven Updates: Diagrams should recalculate pathways upon input changes (e.g., modifying a decision tree node triggers a cascade of dependent branches).
  • Environmental Integration: Sensors or APIs feed real-time data into visual models (e.g., a Petri net transitioning states based on IoT device inputs).
  • Dynamic Complexity Management: Simplify or abstract subgraphs when user interaction exceeds predefined thresholds (e.g., collapsing nested decision hierarchies).
  • Core Requirement: Adaptability ≠ Real-Time Rendering A diagram’s responsiveness depends on precomputed logic branches (e.g., caching decision paths) rather than brute-force recalculations during interaction.
    Implementation Steps:
    1. Define Interaction Triggers: Identify user actions (e.g., node selection, slider adjustments) or external events (e.g., API polling) that require diagram updates.
      • Example: A circuit logic diagram highlights error pathways when a user selects a faulty component.
      • Use JavaScript event listeners (`addEventListener`) for DOM-based diagrams or WebSocket streams for distributed systems.
    2. Modular Logic Layers: Separate the visual representation from the computational core (e.g., a WebAssembly module handling Petri net transitions while the frontend renders states).
      • Tools: D3.js for SVG-based diagrams, Mermaid.js for text-to-diagram conversion, or custom WebGL shaders for high-performance visualizations.
    3. State Persistence: Store diagram configurations in session storage or a database to restore user progress (e.g., saving a decision tree’s pruned branches).

    Color-Coded Logic Pathways and Error Propagation Visualization

    Visual emphasis via color coding reduces cognitive load in complex systems by directing attention to critical connections. This technique is particularly effective in:
  • Circuit Design: Highlighting signal paths where faults propagate (e.g., red for short circuits, yellow for degraded signals).
  • Workflow Automation: Marking dependencies in business logic (e.g., green for completed tasks, blue for pending approvals).
  • Debugging: Tracing execution flows in multi-threaded systems (e.g., time-color gradients to show thread interleaving).
  • Color Mapping Strategies:

    1. Semantic Consistency: Align colors with domain standards (e.g., IEEE 315 for circuit symbols or ISO 9555 for traffic signals).
      • Example: Use #FF0000 for "critical failure" pathways and #00FF00 for "optimal paths" in a routing algorithm.
    2. Dynamic Thresholds: Adjust color intensity based on metrics (e.g., a heatmap where pathway opacity correlates with error frequency).
      • Implementation: CSS `linear-gradient` or Canvas API for smooth transitions between states.
    3. Accessibility Compliance: Ensure colorblind-friendly palettes (e.g., Viridis or Cividis scales) and provide text labels for critical nodes.
    Example: Error Propagation in a Logic Gate Circuit

    AND Gate
    / \
    A B
    \ /

    OUT

    - Visualization: If `A` fails, the pathway from `A` to `OUT` is rendered in #FF0000, while `B`’s path remains neutral (#CCCCCC).

  • Code Snippet (Pseudocode):
  • function highlightErrorPath(node, errorType) {
    const path = getPathToOutput(node);
    path.forEach(segment => {
    segment.style.stroke = errorType === "short" ? "#FF0000" : "#FFFF00";
    segment.style.strokeWidth = "3px";
    });
    }

    Responsive HTML Tables for Logic Symbol Mapping

    A structured table mapping visual logic symbols to computational equivalents ensures consistency across documentation, educational materials, and API references. Mobile adaptability is achieved via `
    SymbolDescriptionComputational EquivalentUse Case
    ∧ Logical AND a && b (JavaScript), a ∧ b (SQL) Circuit design, access control policies
    ⊕ XOR (exclusive OR) a ^ b (Python), a XOR b (Excel) Parity checks, game AI decision trees

    Responsive Enhancements:

    1. Stacked Layout for Mobile: Use CSS `@media` to stack columns vertically on screens <600px wide.

      @media (max-width: 600px) {
      table, thead, tbody, th, td, tr { display: block; }
      thead tr { position: absolute; top: -9999px; }
      tr { border: 1px solid #ccc; margin-bottom: 10px; }
      td { border: none; border-bottom: 1px solid #eee; }
      td:before { content: attr(data-label); font-weight: bold; display: inline-block; width: 120px; }
      }

    2. Interactive Tooltips: Add `title` attributes or JavaScript-based popups for symbol explanations.
    3. Search Functionality: Implement client-side filtering (e.g., using List.js) to locate symbols by use case.

    Generating Text-Based Logic Maps for Multi-Layered Hierarchies

    ASCII art and Markdown tables provide lightweight alternatives for documenting logic flows, especially in environments lacking graphical tools (e.g., terminals, collaborative text editors). Multi-layered hierarchies are represented using indentation, brackets, or numbered steps.

    ASCII Art Techniques:

    1. Tree Structures: Use `/`, `\`, and `|` for branching logic.
      • Example: A decision tree for loan approval:

        [Start]
        |
        v
        [Income > $50k] → [Yes] → [Approved]
        → [No] → [Rejected]

    2. State Machines: Enclose states in boxes (`[]`) and transitions with arrows (`→`).
      • Example: A traffic light system:

        [Red] → [Timer Expires] → [Yellow] → [

        Ethical and Practical Limits of Logic Mashups in Computational Systems

        Logic mashups—integrations of heterogeneous logic systems (e.g., probabilistic, symbolic, and neural reasoning)—enhance computational flexibility but introduce ethical and technical risks. Adversarial inputs, unintended biases, and structural vulnerabilities arise when disparate logic paradigms are combined without rigorous validation. These challenges necessitate systematic auditing frameworks to ensure fairness, transparency, and robustness, particularly in high-stakes applications like autonomous decision-making or regulatory compliance. Trade-offs between performance (e.g., predictive accuracy) and interpretability (e.g., explainability of reasoning) further complicate integration, requiring balanced design choices that align with domain-specific constraints.

        The interplay between logic systems exposes latent flaws that automated testing protocols must address, including edge-case failures, circular dependencies, and ignored constraints. Below, structured analyses outline key risks, audit strategies, and trade-off considerations, alongside actionable red flags for flawed logic integration.

        Unintended Biases and Vulnerabilities in Logic Mashups

        Combining logic systems amplifies biases inherent in individual components, particularly when data-driven (e.g., neural networks) and rule-based (e.g., symbolic logic) models interact. Adversarial inputs exploit mismatches in assumption spaces—for example, a deep learning model trained on biased datasets may override symbolic constraints with high confidence, producing discriminatory outcomes. Real-world cases include:
      • Algorithmic discrimination: A hiring tool integrating resume parsing (NLP) with rule-based eligibility checks may favor candidates from specific demographic groups due to training data imbalances, even if symbolic filters are applied post-hoc.
      • Exploitable vulnerabilities: Hybrid systems merging cryptographic logic with machine learning (e.g., for access control) may fail under adversarial perturbations, such as gradient-based attacks that bypass symbolic safeguards.
      • Concept drift misalignment: Temporal shifts in data distributions (e.g., evolving cybersecurity threats) can cause symbolic rules to conflict with learned patterns, leading to false positives/negatives in critical systems like fraud detection.
      • Key mechanisms of bias propagation:

        "Bias amplification occurs when a logic mashup’s aggregation function (e.g., weighted averaging, ensemble voting) disproportionately amplifies errors from biased submodels, particularly if their confidence scores are miscalibrated."
        Mitigation requires bias audits at integration points, including:
      • Counterfactual testing: Evaluating system behavior under perturbed inputs representing underrepresented groups.
      • Fairness-aware loss functions: Penalizing deviations from demographic parity or equalized odds during training.
      • Constraint satisfaction validation: Ensuring symbolic rules enforce fairness metrics (e.g., "no attribute X shall influence decision Y").
      • Strategies for Auditing Logic Connections

        Automated testing protocols must verify three dimensions: fairness, transparency, and robustness. Below are structured approaches tailored to hybrid logic systems.

        Fairness Auditing

        Fairness in logic mashups hinges on detecting disparate impact across submodels. Techniques include:
        • Disparate Impact Analysis (DIA):
          Compare error rates (e.g., false positives) across protected groups (e.g., gender, race) using statistical parity tests. For example, if a medical diagnosis system (combining neural and rule-based logic) misclassifies 20% of cases for Group A but 5% for Group B, flag the integration for bias.
        • Causal Inference for Attribution:
          Deploy structural causal models (SCMs) to isolate the contribution of each logic component to biased outcomes. Tools like DoWhy (Python) can trace how a neural network’s feature importance conflicts with symbolic constraints.
        • Adversarial Fairness Training:
          Train a secondary "fairness classifier" to detect and correct bias during inference. For instance, in a loan approval mashup, this classifier could override neural predictions if symbolic rules are violated for protected attributes.

        Transparency and Explainability

        Hybrid systems obscure reasoning paths, necessitating model-agnostic interpretability methods:
        • Logic Decomposition:
          Partition the system into modular components (e.g., "Module A: Neural feature extraction," "Module B: Symbolic constraint solver") and generate explanations for each. Use SHAP values for neural parts and rule traceability for symbolic parts.
        • Counterfactual Explanations:
          Generate minimal input perturbations required to change the system’s output, highlighting logic interactions. For example, in a legal contract analysis mashup, show how altering a clause’s phrasing (symbolic) affects the neural sentiment score.
        • Dynamic Visualization:
          Employ interactive graphs (e.g., D3.js) to map data flow between logic layers, annotating confidence scores, rule activations, and confidence mismatches.

        Robustness Validation

        Robustness ensures the system withstands adversarial or edge-case inputs. Protocols include:
        • Formal Verification for Symbolic Components:
          Use tools like Z3 or KeY to verify that symbolic rules hold under all possible input combinations, especially where they interface with probabilistic models.
        • Adversarial Robustness Testing:
          Apply gradient-based attacks (e.g., FGSM, PGD) to neural components while monitoring symbolic guardrails. Measure the percentage of attacks that bypass constraints.
        • Edge-Case Stress Testing:
          Inject inputs designed to expose logic conflicts, such as:
          • Inputs violating symbolic preconditions (e.g., negative ages in a demographic filter).
          • Ambiguous data (e.g., handwritten text misclassified by OCR, then misinterpreted by symbolic rules).
          • Temporal inconsistencies (e.g., a time-series forecast conflicting with a static rule).

        Trade-offs Between Performance and Interpretability

        Merging high-complexity logic models (e.g., deep learning + first-order logic) optimizes performance but sacrifices interpretability, creating a precision-recall-explainability trilemma. Below are quantifiable trade-offs and mitigation strategies.
        Performance Metric Interpretability Impact Example Scenario Mitigation Strategy
        Predictive Accuracy

        High accuracy from neural components obscures symbolic constraints, reducing trust. Users cannot trace decisions to specific rules.

        A fraud detection system using LSTMs for anomaly scoring but symbolic rules for whitelisting VIPs. If the LSTM flags a VIP transaction as fraudulent, the system may override rules without explanation.

        Implement confidence-thresholded overrides: Only allow symbolic rules to override neural outputs if their confidence exceeds a domain-specific threshold (e.g., 90%).

        Latency

        Real-time symbolic reasoning (e.g., theorem proving) conflicts with low-latency neural inference, forcing trade-offs in deployment.

        An autonomous vehicle’s path planning system combining reinforcement learning (RL) for trajectory optimization with symbolic safety constraints. RL may propose unsafe maneuvers that symbolic checks cannot validate in time.

        Use asynchronous validation: Run symbolic checks on a subset of critical decisions (e.g., every 10th maneuver) or deploy lightweight symbolic approximations (e.g., SAT solvers with bounded search).

        Scalability

        Symbolic systems scale poorly with input dimensionality, while neural networks excel in high-dimensional spaces but lack generalization guarantees.

        A recommendation system combining collaborative filtering (neural) with content-based rules (symbolic). Neural embeddings may capture latent biases not addressed by symbolic filters.

        Apply hybrid abstraction: Use neural networks to learn compact representations (e.g., via autoencoders) that symbolic rules can operate on efficiently.

        Key insight:
        "The optimal trade-off depends on the risk tolerance of

        Future-Proofing Logic Systems for Scalability

        Modular logic architectures represent a paradigm shift in system design, enabling organizations to adapt to evolving computational demands without sacrificing stability or performance. By decoupling logic components into autonomous, interchangeable modules—such as microservices or plug-and-play inference engines—systems achieve resilience against technological obsolescence, regulatory shifts, and exponential data growth. This approach aligns with distributed computing principles, where scalability is not an afterthought but a foundational requirement.

        The scalability of logic systems hinges on their ability to maintain consistency, efficiency, and adaptability across heterogeneous environments. Distributed architectures, such as blockchain-based consensus mechanisms or federated learning networks, introduce complexities in latency, synchronization, and fault tolerance. Future-proofing these systems requires proactive strategies to mitigate these challenges while ensuring compliance with dynamic regulatory frameworks, such as GDPR or sector-specific data sovereignty laws.

        Modular Logic Architectures and Seamless Updates

        Modular logic architectures decompose complex decision pipelines into discrete, independently deployable units. This design philosophy mirrors the principles of Service-Oriented Architecture (SOA) and Microservices, where each module encapsulates a specific logic function—e.g., data validation, hint-based inference, or regulatory compliance checks. The key advantage lies in zero-downtime updates: a single module can be revised, patched, or replaced without disrupting the entire system, provided interfaces (APIs, event triggers) remain consistent.

        For instance, in a financial risk assessment system, a module responsible for GDPR-compliant data anonymization can be updated to incorporate new pseudonymization techniques without altering the core risk-scoring algorithm. Similarly, in healthcare diagnostics, a plug-and-play module for interpreting new biomarker data can integrate into an existing pipeline without requiring a full system overhaul. The trade-off involves managing inter-module dependencies, which necessitates robust contract-first design—where module interfaces are defined before implementation—and versioning strategies to ensure backward compatibility.

        Key Principle: "A system’s scalability is proportional to the granularity of its modular components and the efficiency of their orchestration."

        Scaling Logic Connections Across Distributed Systems

        Distributed logic systems, such as those leveraging blockchain consensus or federated learning, introduce latency and synchronization challenges that traditional monolithic architectures avoid. Scaling logic connections in these environments requires a multi-layered approach:

        1. Consensus and Synchronization Overheads
        Distributed ledgers (e.g., Ethereum, Hyperledger Fabric) introduce consensus delays (e.g., Proof-of-Stake or Practical Byzantine Fault Tolerance) that can bottleneck logic execution. For example, a supply chain verification system using smart contracts may experience 5–10 second delays per transaction, limiting real-time hint-based logic updates. Mitigation strategies include:

      • Off-chain computation: Executing non-critical logic locally and anchoring only critical hashes on-chain.
      • Layer-2 solutions: Leveraging rollups (e.g., Optimistic Rollups) to batch and parallelize logic operations.
      • 2. Federated Learning Latency
        In federated learning, where logic models are trained across decentralized nodes, communication latency between clients and a central aggregator can degrade performance. Techniques to optimize include:

      • Model compression: Quantizing or pruning models to reduce transmission overhead.
      • Asynchronous updates: Allowing nodes to contribute updates at variable intervals, trading freshness for scalability.
      • 3. Event-Driven Orchestration
        Logic connections in distributed systems benefit from event sourcing and CQRS (Command Query Responsibility Segregation) patterns. For example, a real-time fraud detection system might use Kafka to stream transaction events, with separate logic modules (e.g., anomaly detection, rule engines) processing data in parallel. This decouples producers and consumers, improving throughput.

        Latency Benchmark: "In a federated learning system with 1,000 nodes, reducing model size by 50% can cut synchronization latency by ~30% under typical network conditions (100ms average RTT)."

        Adapting to Evolving Data Schemas and Regulatory Changes

        Logic systems must evolve alongside data schemas and regulatory landscapes without requiring systemic rewrites. This adaptability is achieved through:

        1. Schema Versioning and Backward Compatibility
        Tools like Apache Avro or Protocol Buffers enable versioned schemas, allowing logic modules to handle both old and new data formats. For example, a customer onboarding system can process legacy JSON records alongside updated Avro schemas by defining union types or default values for deprecated fields.

        2. Regulatory Compliance as a Modular Layer
        Compliance requirements (e.g., GDPR’s "right to erasure") can be encapsulated in policy-as-code modules that inject logic dynamically. For instance:

      • A data retention module triggers automated deletion workflows when a user requests data removal, integrating with the core logic pipeline via event hooks.
      • Differential privacy can be applied as a post-processing layer in federated learning, ensuring anonymity without altering the underlying model training logic.
      • 3. Automated Schema Migration
        Systems like Apache NiFi or Debezium enable real-time schema evolution by capturing change data capture (CDC) events. For example, if a healthcare analytics system updates its patient record schema to include genetic data, CDC streams can propagate these changes to dependent logic modules (e.g., genetic risk predictors) without manual intervention.

        Regulatory Adaptation Framework:
        *"Logic systems should treat compliance as a first-class citizen, with:
      • Modular policy engines (e.g., Open Policy Agent).
      • Audit trails for all data-processing decisions.
      • Automated impact assessments for schema changes."*
      • Checklist: Key Metrics for Logic System Health

        Monitoring logic system performance requires a balanced set of metrics that reflect throughput, accuracy, and adaptability. Below is a structured checklist categorized by operational and regulatory dimensions:

        Performance Metrics
        Logic systems should track the following to ensure scalability and efficiency:

        • Throughput (Operations/Second): Measures the rate at which logic modules process inputs (e.g., API calls, event streams). Benchmark against peak load requirements (e.g., 10,000 transactions/sec for payment systems).
        • Latency Percentiles (P50, P99, P99.9): Identifies bottlenecks in distributed logic flows. For example, a P99 latency of 500ms in a fraud detection system may indicate a slow consensus mechanism.
        • Module Response Time Distribution: Compares response times across modules to detect skewed workloads (e.g., a single hint-generation module taking 3x longer than others).
        • Resource Utilization (CPU, Memory, I/O): Tracks saturation points in containerized or serverless environments (e.g., AWS Lambda cold starts affecting logic execution).
        Accuracy and Reliability Metrics
        Ensuring logic correctness in dynamic environments:
        • Hint Accuracy (Precision/Recall): Validates the effectiveness of hint-based logic (e.g., 95% precision in anomaly detection). Use confusion matrices for multi-class scenarios.
        • Error Rate (False Positives/Negatives): Monitors compliance logic errors (e.g., GDPR consent mismatches) and their impact on downstream systems.
        • Consistency Across Distributed Nodes: In federated systems, measure model drift (e.g., 5% deviation in federated learning aggregator outputs).
        • Retry and Backoff Metrics: Tracks transient failures (e.g., 10% of logic calls requiring retries due to network partitions).
        Adaptability and Compliance Metrics
        Assessing resilience to schema and regulatory changes:
        • Schema Evolution Rate: Number of schema updates per month and their impact on logic module compatibility (e.g., 2 updates/month with 0% breaking changes).
        • Compliance Audit Frequency: Automated checks for GDPR/CCPA violations in logic pipelines (e.g., weekly scans for data retention violations).
        • Module Update Cadence: Time-to-deploy for critical logic patches (e.g., <24 hours for security fixes).
        • Dependency Vulnerability Score: Measures risks from outdated libraries in logic modules (e.g., CVSS score >7.0 in any dependency).
        Distributed System-Specific Metrics
        Tailored for blockchain, federated learning, or multi-cloud deployments:
        • The mastery of logic connection systems hinges on balancing theoretical depth with pragmatic adaptability, where every gate, rule, or hint is purposefully integrated to serve a greater computational goal. From foundational Boolean logic to cutting-edge fuzzy and probabilistic hybrids, the techniques outlined here empower practitioners to construct systems that are not only efficient but also interpretable and scalable. The future of logic mashups lies in modular, hint-driven architectures that anticipate change—whether in data schemas, regulatory landscapes, or user behavior—while mitigating risks like bias or circular dependencies. By adopting the frameworks and tools discussed, professionals can future-proof their systems, ensuring they remain both performant and ethically sound in an era of exponential complexity.

          Ultimately, the ultimate guide to logic connection hints transcends mere technical instruction; it is a roadmap for building intelligent systems that learn, adapt, and thrive. Whether optimizing autonomous decision trees or auditing AI fairness, the principles here provide actionable insights to elevate logic integration from a functional necessity to a strategic advantage. The key lies in treating logic not as static rules but as a living, evolving framework—one that continuously refines its connections based on data, context, and ethical imperatives.