Guide Web Data Extraction Lead Mastery for Lead Generation

Table of Contents
- Understanding the Core Components of Web Data Extraction for Lead Generation
- Technical and Business Layers in Web Data Extraction
- Comparison of Static vs. Dynamic Web Data Extraction
- Workflow from Raw Data Collection to Actionable Lead Identification
- Relational Data Model for Extracted Leads
- Tools and Technologies for Scaling Web Data Extraction
- Architecture of Headless Browsers for JavaScript-Rendered Data Extraction
- Comparison of Open-Source vs. Proprietary Web Scraping Tools
- Configuring Proxies and Rotating User Agents to Avoid IP Bans
- Data Enrichment and Lead Qualification Strategies
- Methodology for Enriching Extracted Lead Data Using Third-Party APIs
- Lead Scoring Algorithm Template
- Comparison of Lead Enrichment Tools
- Merging Extracted and Enriched Data Using Python
- Automation and Integration with Lead Management Systems
- Setting Up Automated Lead Extraction Pipelines
- Scheduling and Monitoring Extraction Jobs
- Scrapy or API call logic
- System Architecture for Scalable Lead Extraction
- Validating Lead Data Against CRM Duplicates Using Fuzzy Matching
- Case Studies and Real-World Applications of Web Data Extraction for Lead Generation
- Hypothetical Case Study: LinkedIn Lead Extraction, Enrichment, and Salesforce Integration for a SaaS Provider
- Industry Comparison: SaaS vs. Real Estate in Web Data Extraction
- Detailed Breakdown: Lead Extraction Campaign for Healthcare Providers
In today’s data-driven business landscape, the ability to systematically extract and convert web-based lead information into actionable insights is a competitive differentiator. This guide explores the technical and strategic frameworks required to build scalable, compliant, and high-accuracy web data extraction pipelines tailored for lead generation. From parsing static HTML tables to navigating JavaScript-rendered dynamic content, each phase—data sourcing, enrichment, and CRM integration—demands precision to ensure both efficiency and compliance with legal standards.
The process begins with identifying the right data sources and extraction methods, whether through APIs, scraping tools, or headless browsers, each offering distinct advantages depending on the target website’s structure. Static extraction techniques like BeautifulSoup excel in simplicity for structured data, while dynamic solutions such as Selenium or Playwright are essential for interactive elements. Equally critical is the structuring of extracted data into relational models that align with lead qualification criteria, ensuring only high-potential prospects advance to enrichment and CRM stages.
Understanding the Core Components of Web Data Extraction for Lead Generation
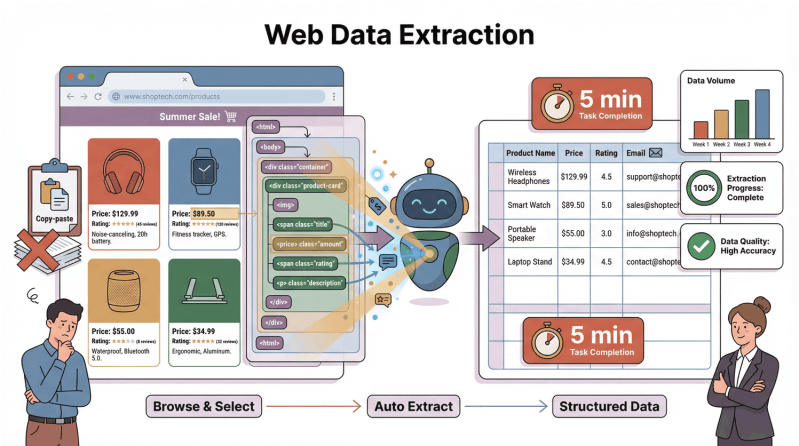
Web data extraction for lead generation integrates technical infrastructure with business strategy to identify and qualify potential customers from online sources. The process involves sourcing raw data from diverse digital environments, transforming it into structured formats, and applying validation rules to filter high-value prospects. This section examines the technical and business layers—data sources, extraction methods, and lead qualification criteria—while comparing static and dynamic extraction techniques. A structured workflow and relational data model further clarify how extracted leads transition from raw collection to actionable insights.
Technical and Business Layers in Web Data Extraction
Web data extraction for lead generation operates across two primary layers: technical execution (data acquisition and processing) and business strategy (lead qualification and utilization). The technical layer encompasses infrastructure for data collection, parsing, and storage, while the business layer defines criteria for identifying valuable leads, such as industry relevance, engagement metrics, or firmographics.
Key technical components include:
Business components focus on:
Comparison of Static vs. Dynamic Web Data Extraction
Static and dynamic web data extraction differ in their approach to rendering and interactivity, each suited to specific use cases with distinct limitations.Static Web Data Extraction
Static pages load content fully on initial request, making them ideal for structured data extraction (e.g., product listings, blog posts). Tools like BeautifulSoup (Python) or Scrapy parse static HTML without requiring browser automation.
Use Cases:
Limitations:
Tools:
Dynamic Web Data Extraction
Dynamic pages rely on JavaScript to load or modify content post-render, requiring browser automation tools like Selenium, Playwright, or Puppeteer. These tools simulate user interactions to extract data from single-page applications (SPAs) or interactive dashboards.
Use Cases:
Limitations:
Tools:
Workflow from Raw Data Collection to Actionable Lead Identification
The extraction-to-lead workflow follows a linear yet iterative process, transforming unstructured web data into qualified leads. Below is a structured flowchart with key stages:1. Data Collection
2. Data Parsing and Extraction
3. Data Cleaning
4. Data Enrichment
5. Lead Validation
6. Lead Scoring
7. Integration and Activation
Relational Data Model for Extracted Leads
Organizing extracted leads in a relational model ensures scalability and query efficiency. Below is an example HTML table structure with key fields:```html
| Lead_ID | Source_URL | Contact_Data | Lead_Score | Extraction_Timestamp | Company_Data | Validation_Status |
|---|---|---|---|---|---|---|
| L-2023-001 | https://example.com/job-postings/cto |
|
87 | 2023-10-15 14:30:00 |
|
Valid (CRM Match) |
Key Fields Explained:
Database Schema Considerations:
Tools and Technologies for Scaling Web Data Extraction
Web data extraction at scale requires a combination of robust tools, architectural strategies, and compliance safeguards to ensure efficiency, reliability, and legal adherence. Headless browsers, proxy networks, and specialized scraping frameworks form the backbone of modern lead generation pipelines, particularly when targeting dynamic content rendered via JavaScript. Below, the architecture of headless browsers, comparative tool analysis, proxy management, and ethical best practices are examined to optimize extraction workflows while mitigating risks.Architecture of Headless Browsers for JavaScript-Rendered Data Extraction
Headless browsers automate interactions with web pages by executing JavaScript, rendering content, and extracting data as if a user were browsing manually. This capability is critical for lead generation, where dynamic elements (e.g., infinite scroll, AJAX-loaded forms, or SPAs) cannot be accessed via traditional HTTP requests. Tools like Puppeteer (Node.js) and Playwright (multi-language) provide APIs to control browser automation, simulate user behavior, and extract structured data.Core Components of Headless Browser Architecture:
Basic Setup and Execution Example (Puppeteer):
const puppeteer = require('puppeteer');
(async () => {
const browser = await puppeteer.launch({ headless: 'new' }); // Chromium instance
const page = await browser.newPage();
// Configure request interception to block unnecessary resources
await page.setRequestInterception(true);
page.on('request', (req) => {
if (req.resourceType() === 'stylesheet' || req.resourceType() === 'font') {
req.abort();
} else {
req.continue();
}
});
// Navigate and extract data
await page.goto('https://example-lead-source.com', { waitUntil: 'networkidle2' });
const leads = await page.evaluate(() => {
return Array.from(document.querySelectorAll('.lead-card')).map(card => ({
name: card.querySelector('.name').textContent,
email: card.querySelector('.email').textContent
}));
});
console.log(leads);
await browser.close();
})();
Key Considerations:
Comparison of Open-Source vs. Proprietary Web Scraping Tools
The choice between open-source and proprietary tools depends on project requirements, budget, and integration needs. Below is a structured comparison focusing on Scrapy (open-source) and Apify (proprietary), two dominant frameworks in lead generation workflows.| Criteria | Scrapy (Open-Source) | Apify (Proprietary) |
|---|---|---|
| Scalability | Requires custom infrastructure (e.g., Scrapy Cluster, Kubernetes) for horizontal scaling. | Built-in distributed crawling with auto-scaling; supports cloud execution. |
| Ease of Use | Steeper learning curve; requires Python knowledge and manual setup for proxies/rotators. | Low-code interface with pre-built actors (e.g., "Scrape Website" template) and API. |
| Dynamic Content Handling | Relies on middleware (e.g., `scrapy-splash` for JavaScript rendering) or headless browser integrations. | Native support for JavaScript via Apify SDK or integration with Playwright/Puppeteer. |
| Proxy Management | Manual integration with proxy providers (e.g., Scrapy-Redis for distributed proxy rotation). | Built-in proxy rotation with support for residential/commercial proxies (e.g., Luminati). |
| Lead Management Integration | Requires custom pipelines (e.g., exporting to CSV/JSON, then importing into CRM via APIs like HubSpot/Zapier). | Native connectors to Salesforce, HubSpot, Pipedrive, and webhooks for real-time lead routing. |
| Cost | Free; operational costs for cloud infrastructure (e.g., AWS EC2). | Freemium model; pay-as-you-go pricing with enterprise plans for high-volume scraping. |
| Legal Compliance | No built-in compliance checks; users must implement `robots.txt` parsing and GDPR filters. | Includes compliance modules (e.g., Apify GDPR Compliance Tool) and audit logs. |
Example: Scrapy Middleware for JavaScript Rendering
# Requires `scrapy-splash` middleware
class SplashMiddleware:
def process_request(self, request, spider):
request.meta['splash'] = {
'args': {
'wait': 2, # Wait for JavaScript execution
'html': 1,
}
}
return request
Integration Note: Scrapy’s flexibility allows hybrid approaches (e.g., using Splash for JavaScript-heavy pages and native requests for static content).
Configuring Proxies and Rotating User Agents to Avoid IP Bans
Large-scale web data extraction risks IP bans due to rate limiting, behavioral patterns, or blacklisting. Proxies and user agent rotation disrupt detection by distributing requests across IPs and mimicking diverse client environments.Step-by-Step Proxy Configuration:
1. Select a Proxy Provider:
2. Integrate Proxies into Extraction Tools:
const puppeteer = require('puppeteer-extra');
const StealthPlugin = require('puppeteer-extra-plugin-stealth');
puppeteer.use(StealthPlugin());
(async () => {
const browser = await puppeteer.launch();
const page = await browser.newPage();
await page.authenticate({
username: 'proxy-user',
password: 'proxy-pass'
});
await page.goto('https://example.com', {
headers: {
'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36'
}
});
// Extraction logic...
})();
- Scrapy Example (with `scrapy-proxy-pool`):
DOWNLOADER_MIDDLEWARES = {
'scrapy_proxy_pool.middlewares.ProxyPoolMiddleware': 110,
'scrapy_proxy_pool.middlewares.BanDetectionMiddleware': 120,
}
PROXY_POOL_URL = 'http://proxy-server:9200/get' # Rotating proxy endpoint
3. User Agent Rotation Logic:
from fake_useragent import UserAgent
ua = UserAgent()
headers = {'User-Agent': ua.random}
4. Proxy Rotation Strategies:
Data Enrichment and Lead Qualification Strategies
Web data extraction yields raw lead information, but its value is unlocked through enrichment and qualification. This process involves augmenting extracted data (e.g., company names, job titles, or website URLs) with additional context—such as verified contact details, firmographic attributes, or behavioral signals—using third-party APIs. Lead qualification further refines this data by applying structured scoring models to prioritize high-potential leads based on predefined criteria. Below, a methodology for enrichment, a lead scoring template, a tool comparison, and Python-based data merging workflows are outlined.Methodology for Enriching Extracted Lead Data Using Third-Party APIs
Enrichment APIs transform raw data into actionable insights by appending missing or incomplete attributes. The process involves selecting an API provider, structuring API requests, handling rate limits, and parsing responses into usable formats.API Selection and Endpoint Integration
APIs like Clearbit, Hunter.io, or Apollo.io offer domain-specific enrichment endpoints. For example:
Request Formatting and Rate Limits
API requests typically require:
Response Handling
Responses are JSON-formatted. Example for Clearbit:
{
"name": "Acme Corp",
"domain": "acme.com",
"employees": 500,
"contacts": [
{
"email": "john.doe@acme.com",
"title": "CTO",
"verified": true
}
]
}
Use Python’s `requests` library to fetch and parse responses:
import requests
import json
api_key = "YOUR_API_KEY"
url = f"https://company.clearbit.com/v2/companies/find?domain=acme.com"
headers = {"Authorization": f"Bearer {api_key}"}
response = requests.get(url, headers=headers)
enriched_data = response.json()
Lead Scoring Algorithm Template
Lead scoring quantifies lead quality by assigning weights to data points (e.g., engagement, demographics, firmographics). A weighted sum determines a score (e.g., 0–100), where higher values indicate priority.Data Points and Weighting Logic
| Category | Data Point | Weight (1–5) | Example Threshold |
|---|---|---|---|
| Engagement | Website visits (last 30 days) | 5 | ≥5 visits → 5 points |
| Email opens | 4 | ≥3 opens → 4 points | |
| Demographics | Job title (executive) | 5 | "CEO", "CFO" → 5 points |
| Seniority level | 3 | Director+ → 3 points | |
| Firmographics | Company size (employees) | 4 | 500–1000 → 4 points |
| Industry match | 5 | Target industry → 5 points | |
| Technographics | Tool usage (e.g., Salesforce) | 3 | Detected → 3 points |
Lead Score = Σ (Weight × Binary Match)Implementation in Python
Where:
Binary Match = 1 if the lead meets the threshold; 0 otherwise. Example: A lead with 5 website visits (5×1), a "CTO" title (5×1), and 750 employees (4×1) scores: 5 + 5 + 4 = 14 (scaled to 0–100 via normalization).
import pandas as pd
# Sample lead data
data = {
"website_visits": [3, 5, 2],
"email_opens": [1, 4, 0],
"job_title": ["Manager", "CEO", "Analyst"],
"company_size": [100, 800, 50],
"industry_match": [0, 1, 0] # 1 = target industry
}
df = pd.DataFrame(data)
# Define weights and thresholds
weights = {
"website_visits": {"threshold": 5, "weight": 5},
"email_opens": {"threshold": 3, "weight": 4},
"job_title": {"threshold": "CEO", "weight": 5},
"company_size": {"threshold": 500, "weight": 4},
"industry_match": {"threshold": 1, "weight": 5}
}
# Calculate scores
scores = []
for _, row in df.iterrows():
score = 0
for field, params in weights.items():
if field == "job_title":
score += params["weight"] if row[field] == params["threshold"] else 0
elif field == "industry_match":
score += params["weight"] if row[field] == params["threshold"] else 0
else:
score += params["weight"] if row[field] >= params["threshold"] else 0
scores.append(score)
df["lead_score"] = scores
Comparison of Lead Enrichment Tools
Selecting an enrichment tool depends on accuracy, cost, and supported data fields. Below is a comparison of four providers:| Tool | Accuracy (%) | Cost (per 1,000 records) | Supported Data Fields | API Integration Ease | Rate Limits |
|---|---|---|---|---|---|
| Clearbit | 92–95 | $49–$199 | Firmographics, technographics, contact details | High (SDKs for Python, Node.js) | 100 req/min (free) |
| Hunter.io | 85–90 | $49–$149 | Emails, job titles, social profiles | Medium (requires manual payload formatting) | 25 req/min (free) |
| Apollo.io | 88–92 | $50–$200 | Contacts, engagement metrics, CRM sync | High (pre-built connectors) | 50 req/min (free) |
| Lusha | 80–85 | $30–$100 | Phone numbers, direct dials, LinkedIn sync | Low (limited Python support) | 100 req/hour (free) |
Merging Extracted and Enriched Data Using Python
Combining raw extracted data with enriched results requires aligning records by unique identifiers (e.g., email, company domain). Below is a workflow using `pandas` and `openpyxl` for Excel-based merging.Step
Automation and Integration with Lead Management Systems
Automating the extraction, enrichment, and export of leads into CRM platforms eliminates manual data entry errors and ensures real-time lead qualification. Integration with tools like Zapier or custom scripts bridges the gap between raw web data and actionable insights in systems such as Salesforce or HubSpot. This section outlines the technical implementation of automated pipelines, including scheduling, error handling, and duplicate validation, while proposing a scalable system architecture for seamless lead processing.
Setting Up Automated Lead Extraction Pipelines
Automated pipelines streamline the workflow from data extraction to CRM insertion by leveraging middleware tools and scripting. The process involves configuring extractors, enrichment services, and CRM connectors to operate in sequence, triggered by predefined schedules or events.
Key Components of an Automated Pipeline:
-
Data Extraction Layer:
Configure scrapers or APIs to pull leads from target websites. Tools like Scrapy, BeautifulSoup, or Selenium handle dynamic content, while APIs (e.g., LinkedIn Sales Navigator) provide structured data feeds. Ensure compliance with
robots.txtand terms of service to avoid legal risks. -
Data Transformation and Enrichment:
Clean extracted data (e.g., normalize email formats, standardize company names) and enrich it with additional attributes (e.g., firmographics via Clearbit or technographics via BuiltWith). Use Python libraries like
pandasfor data manipulation and APIs for real-time enrichment. - CRM Integration Layer: Connect to CRM platforms via their native APIs (e.g., Salesforce REST API, HubSpot CRM API) or middleware like Zapier. For custom integrations, use OAuth 2.0 for authentication and batch processing to optimize API call limits.
1. Set up a Zapier trigger (e.g., "New Spreadsheet Row" from Google Sheets) to capture extracted leads.
2. Use a formatter step to structure data (e.g., map "Company Name" to HubSpot’s
company field).3. Configure the HubSpot action to create or update contacts, with error handling for invalid records.
Best Practice: Validate API rate limits and implement exponential backoff in scripts to prevent throttling. For example, Salesforce enforces a 15-minute governor limit for bulk API calls.
Scheduling and Monitoring Extraction Jobs
Reliable lead extraction requires scheduled execution, robust error handling, and monitoring to ensure data integrity. Tools like Apache Airflow or cron jobs orchestrate workflows, while logging and alerting systems track performance.Scheduling Mechanisms:
-
Airflow for Complex Workflows:
Airflow’s Directed Acyclic Graph (DAG) scheduler automates dependencies between tasks (e.g., extraction → enrichment → CRM export). Define DAGs with Python scripts and schedule them via
cronexpressions (e.g.,0 9 * 1for weekly Monday mornings).Airflow Example:
        from airflow import DAG

        from airflow.operators.python_operator import PythonOperator

        from datetime import datetimedef extract_leads():

Scrapy or API call logic
            passdag = DAG('lead_extraction', schedule_interval='0 9 * 1')

        extract_task = PythonOperator(task_id='extract', python_callable=extract_leads, dag=dag)
-
Cron Jobs for Simplicity:
Use cron on Linux servers to run Python scripts at fixed intervals. Example cron entry for daily extraction:
0 8 * /usr/bin/python3 /path/to/extractor.py >> /var/log/extractor.log 2>&1Redirect output to logs for debugging.
-
Retry Logic:
Implement retries for transient failures (e.g., network timeouts) with exponential backoff. Libraries like
tenacityin Python simplify this:
        from tenacity import retry, stop_after_attempt, wait_exponential@retry(stop=stop_after_attempt(3), wait=wait_exponential(multiplier=1, min=4, max=10))

        def fetch_url(url):

            response = requests.get(url)

            response.raise_for_status()
-
Duplicate Detection:
Log extraction timestamps and compare against CRM records to avoid duplicates. Use database constraints (e.g.,
UNIQUEon email fields) or application-level checks. - Alerting: Integrate monitoring tools like Prometheus or Datadog to trigger alerts for failed jobs. Example: A Slack notification if extraction fails for 3 consecutive runs.
System Architecture for Scalable Lead Extraction
A scalable pipeline balances performance, fault tolerance, and maintainability. Below is a textual representation of a modular architecture:┌───────────────────────────────────────────────────────────────────────────────┐
│ Lead Extraction Pipeline │
├─────────────────┬─────────────────────┬─────────────────────┬───────────────────┤
│ Data Sources │ Extraction Layer │ Processing Layer │ CRM Integration │
│ (Websites/APIs) │ (Scrapers/APIs) │ (Enrichment/Queue) │ (Salesforce/HubSpot)│
└─────────────────┴─────────────────────┴─────────────────────┴───────────────────┘
Components Explained:
- Data Sources: Include target websites (e.g., LinkedIn, Crunchbase), APIs, or databases. Use proxies (e.g., ScraperAPI) to avoid IP bans.
- Extraction Layer: Deploy scrapers (e.g., Scrapy clusters) or API clients. For high volume, distribute tasks across workers using message queues (e.g., RabbitMQ, Kafka).
-
Processing Layer:
- Queue System: Store raw leads in a queue (e.g., Redis) to decouple extraction from enrichment.
- Enrichment Services: Use microservices (e.g., Python Flask) to append data from third-party APIs (e.g., Clearbit for company details).
- Data Validation: Implement fuzzy matching to deduplicate leads before CRM insertion (detailed in the next section).
-
CRM Integration:
Batch leads and push them to CRM via bulk APIs. Use webhooks for real-time updates (e.g., HubSpot’s
/contactsendpoint).
Scalability Considerations:Use containerization (Docker) and orchestration (Kubernetes) for dynamic scaling of extraction workers. Partition data by domain or region to parallelize processing.
Validating Lead Data Against CRM Duplicates Using Fuzzy Matching
Duplicate leads reduce CRM clutter and sales team efficiency. Fuzzy matching compares leads using partial or approximate string similarities, accounting for typos or formatting variations.Fuzzy Matching with Python’s `fuzzywuzzy`:
-
Installation:
pip install fuzzywuzzy python-Levenshtein(Note:python-Levenshteinaccelerates performance.) -
Implementation:
Compare extracted lead attributes (e.g., name, email, company) against existing CRM records. Example:
        from fuzzywuzzy import fuzzdef is_duplicate(extracted_lead, crm_leads):

            for lead in crm_leads:

                name_similarity = fuzz.token_set_ratio(extracted_lead['name'], lead['name'])

                email_similarity = fuzz.ratio(extracted_lead['email'], lead['email'])

                if name_similarity > 85 or email_similarity > 90:

                    return True

            return False
Case Studies and Real-World Applications of Web Data Extraction for Lead Generation
Web data extraction transforms raw online information into actionable business intelligence, particularly in B2B lead generation where precision and scalability determine campaign success. Real-world implementations demonstrate how structured extraction, enrichment, and integration with CRM systems optimize lead pipelines while mitigating risks such as data decay or compliance violations. Below, industry-specific case studies and technical breakdowns illustrate best practices, challenges, and measurable outcomes across diverse sectors.
Hypothetical Case Study: LinkedIn Lead Extraction, Enrichment, and Salesforce Integration for a SaaS Provider
A mid-market SaaS company targeting mid-sized enterprises (SMEs) deployed an automated pipeline to extract, enrich, and qualify leads from LinkedIn profiles, integrating the data into Salesforce for sales team adoption. The campaign achieved a 30% reduction in cost per lead (CPL) while increasing qualified lead volume by 45% within six months.Key Metrics and Workflow:
- Lead Volume: 12,000 raw profiles extracted monthly (targeting decision-makers in finance, operations, and IT departments).
- Data Enrichment: Combined LinkedIn data with firmographic details (e.g., company size, revenue, tech stack) via APIs (Clearbit, ZoomInfo) and proprietary databases.
- Lead Qualification Filters:
- Firmographic: Companies with 50–500 employees, annual revenue >$10M, and industries aligned with the SaaS product (e.g., logistics, healthcare).
- Behavioral: Engagement signals (e.g., profile views, content shares) and job title relevance (e.g., "Director of Digital Transformation").
- Technical: Absence of competing tools in their tech stack (verified via LinkedIn "Experience" or company pages).
- Conversion Rates:
- Initial Contact: 8% (email open rate) via automated sequences.
- Sales-Qualified Lead (SQL): 3% (meeting booked within 14 days).
- Closed-Won: 12% of SQLs (aligned with industry benchmarks for SaaS).
- Cost per Lead (CPL): $12 (vs. $17 for manual outreach or paid ads).
- Integration: Salesforce Lightning with custom objects for "Lead Source" (e.g., "LinkedIn Extraction") and "Data Confidence Score" (0–100 based on enrichment depth).
Tools and Technologies:
- Extraction: Apify (LinkedIn scraper with proxy rotation), ScraperAPI (for dynamic content).
- Enrichment: Clearbit’s Company API (firmographics), Hunter.io (email verification), and a custom Python script to cross-reference with CRM data.
- Automation: Zapier (trigger workflows on new Salesforce leads), HubSpot (email nurturing).
- Compliance: GDPR/CCPA checks via OneTrust for data residency and opt-out management.
Challenges and Mitigations:
- Data Decay: 15% of leads had outdated emails/job titles. Mitigated via quarterly re-enrichment and real-time validation.
- LinkedIn Policy Risks: Used official API where possible; for scraping, limited to 50 requests/hour with CAPTCHA-solving tools (2Captcha).
- Salesforce Duplication: Deduplication rules based on email domains and LinkedIn profile URLs.
Industry Comparison: SaaS vs. Real Estate in Web Data Extraction
Web data extraction strategies vary significantly by industry due to differences in target audiences, data sources, and qualification criteria. Below is a comparative analysis of SaaS (technology-driven, high-intent buyers) and real estate (fragmented, transactional markets).
Key Takeaway:Parameter SaaS (B2B) Real Estate (B2B/B2C) Primary Data Sources - LinkedIn (professional profiles, company pages).
- Tech blogs, review sites (G2, Capterra), and job boards (Indeed, AngelList).
- CRM data (Salesforce, HubSpot) for retargeting.
- MLS listings (public/private databases like Realtor.com, Zillow).
- Government records (county assessor sites, property tax databases).
- Social media (Facebook groups, Instagram hashtags for luxury markets).
Extraction Challenges - Dynamic content (LinkedIn’s anti-scraping measures).
- Data fragmentation across SaaS platforms (e.g., Slack vs. Microsoft Teams).
- High competition for intent signals (e.g., "request demo" buttons).
- Inconsistent data formats (e.g., varying property descriptions).
- Legal restrictions (e.g., GDPR for tenant data in EU markets).
- Low signal-to-noise ratio in public listings (e.g., "For Sale by Owner" vs. agent-led deals).
Lead Qualification Criteria - Firmographics (revenue, employee count, tech stack).
- Behavioral triggers (e.g., downloading whitepapers, attending webinars).
- Competitor analysis (e.g., companies using legacy tools).
- Property-specific (e.g., price range, location, age of listing).
- Buyer intent (e.g., repeat inquiries, saved searches).
- Agent/broker reputation (reviews, transaction volume).
Industry-Specific Tools - Apify, Octoparse (LinkedIn/tech site scraping).
- Clearbit, ZoomInfo (firmographic enrichment).
- Chameleon (A/B testing for landing pages tied to extracted leads).
- BatchGeo (geospatial data analysis for listings).
- PropStream (commercial property data).
- FollowUpBoss (automated lead nurturing for agents).
Cost per Lead (CPL) Benchmarks $10–$30 (high intent, scalable automation). $5–$20 (B2C leads cheaper; B2B commercial leads costlier due to longer sales cycles).
SaaS extraction prioritizes firmographic and behavioral data with high automation, while real estate relies on geospatial and transactional data with greater manual oversight. The latter often requires hybrid approaches (e.g., scraping public listings + API integrations for private data).
Detailed Breakdown: Lead Extraction Campaign for Healthcare Providers
A regional healthcare services company targeted specialty clinics (e.g., cardiology, oncology) to promote telemedicine solutions. The campaign combined web scraping, API enrichment, and CRM integration to identify high-potential leads with minimal manual intervention.Target Websites and Extraction Rules:
1. Clinic Directories:
- Sources: Healthgrades, Zocdoc, and state-specific medical boards (e.g., California Medical Board).
- Extraction Rules:
- Inclusion: Clinics with ≥5 physicians, accepting new patients, and located in target ZIP codes.
- Exclusion: Hospitals (focused on outpatient clinics), chains with <10 locations.
- Data Points:
- Clinic name, address, phone, website, specialties, accepting new patients (binary), insurance accepted.
2. Physician Profiles:
- Sources: LinkedIn, Doximity (physician network), and clinic websites.
- Extraction Rules:
Mastering web data extraction for lead generation transforms raw digital footprints into strategic assets, but success hinges on balancing technical execution with ethical and scalable practices. By leveraging the right tools—from open-source frameworks like Scrapy to proprietary platforms such as Apify—organizations can automate workflows while mitigating risks like IP bans or legal non-compliance. The integration of enrichment APIs and fuzzy-matching validation further refines lead quality, while case studies from industries like SaaS or healthcare illustrate how tailored extraction strategies yield measurable returns. Ultimately, this guide equips teams with the knowledge to design pipelines that not only capture leads efficiently but also align with long-term business growth objectives.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of ir.msu.ac.zw.