Comprehensive Guide Accessing Real Time Data Systems Efficiently
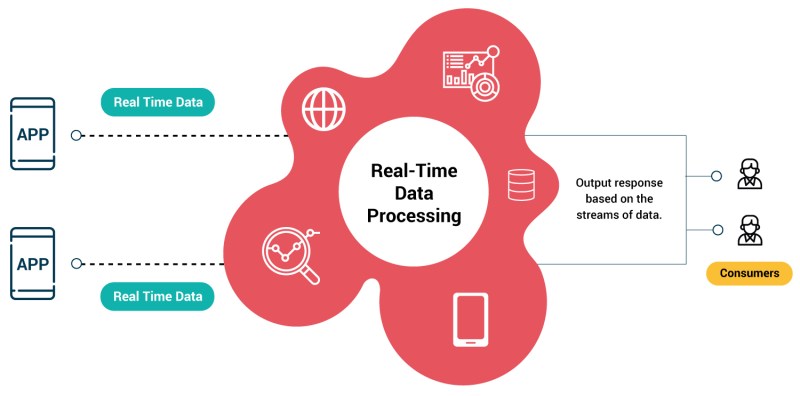
Table of Contents
- Understanding Real-Time Data Access Fundamentals
- Core Principles of Real-Time Data Systems
- Synchronous vs. Asynchronous Real-Time Data Retrieval
- Hardware and Software Requirements for Real-Time Systems
- Conceptual Design of a Real-Time Data Pipeline
- Identifying Bottlenecks in Real-Time Systems
- Methods for Real-Time Data Retrieval
- API-Based Real-Time Data Access Methods
- Setting Up Real-Time Databases for Live Synchronization
- Integrating Real-Time Analytics Tools
- Tools and Platforms for Real-Time Data Access
- Curated List of Open-Source and Commercial Tools
- Configuring a Real-Time Monitoring Dashboard
- Security and Compliance in Real-Time Systems
- Critical Security Measures for Real-Time Systems
- Compliance Checklist for Real-Time Data Access
- Zero-Trust Security Model for Real-Time APIs
- Optimizing Performance for Real-Time Data Access
- Techniques for Reducing Latency in Real-Time Systems
- Load Testing Real-Time APIs with High-Frequency Requests
- Data Compression and Binary Protocols for Throughput Optimization
- Handling Backpressure in Real-Time Streams
Real-time data access has transformed industries by enabling instantaneous decision-making, operational agility, and seamless user experiences. From financial trading platforms to IoT-driven smart cities, the demand for low-latency systems continues to rise, yet many organizations struggle to implement scalable, secure, and high-performance architectures. This guide dissects the foundational principles, technical methodologies, and optimization strategies essential for building or enhancing real-time data pipelines. By examining event-driven architectures, protocol comparisons, and compliance frameworks, readers will gain actionable insights to deploy robust solutions tailored to their specific use cases.
The evolution of real-time systems has shifted from batch processing to streaming architectures, where data flows continuously between sources and consumers. Understanding the trade-offs between synchronous and asynchronous retrieval methods, selecting the right protocols (e.g., WebSockets, MQTT), and addressing security challenges like encryption and zero-trust models are critical steps. Additionally, performance bottlenecks—such as latency, throughput, and packet loss—require systematic monitoring and mitigation to ensure reliability. This resource consolidates best practices, tool comparisons, and industry-specific regulations to equip stakeholders with a comprehensive roadmap for real-time data mastery.
Understanding Real-Time Data Access Fundamentals
Real-time data access systems enable instantaneous decision-making by minimizing the delay between data generation and consumption. These systems are critical in domains such as financial trading, IoT monitoring, autonomous vehicles, and live analytics, where sub-second latency can determine success or failure. Core principles include latency thresholds (defined by use-case requirements, often measured in milliseconds), event-driven architectures (where data flows asynchronously in response to triggers), and streaming protocols (optimized for low-latency, bidirectional communication). Below, the foundational elements of real-time data systems are explored, including architectural trade-offs, hardware/software prerequisites, and pipeline design considerations.Real-time data systems prioritize temporal consistency over batch processing efficiency, necessitating specialized protocols and infrastructure. Latency thresholds vary by application—financial HFT (high-frequency trading) systems may target <10ms, while industrial IoT applications might tolerate 100–500ms. Event-driven architectures decouple producers and consumers, enabling scalability but introducing complexity in state management. Streaming protocols like WebSockets (full-duplex, persistent connections), MQTT (lightweight, publish-subscribe for IoT), and Apache Kafka (distributed, fault-tolerant event logging) address distinct latency and scalability needs. Below, synchronous vs. asynchronous methods are contrasted, followed by hardware/software requirements and pipeline design.
Core Principles of Real-Time Data Systems
Real-time data systems rely on three interdependent principles: low-latency communication, event-driven processing, and scalable state management. Latency thresholds are determined by the critical path—the longest delay between data generation and actionable insight. For example, a 10ms threshold in trading aligns with round-trip latency for order execution, while a 200ms threshold suffices for live sports analytics. Event-driven architectures process data as discrete events (e.g., sensor readings, user clicks) rather than batches, reducing idle time but requiring exactly-once semantics to prevent duplicates or omissions.Streaming protocols optimize for real-time constraints:
Latency vs. Throughput Trade-off:
Real-time systems often sacrifice throughput for latency. For instance, Kafka’s 1ms write latency (with in-memory queues) contrasts with its millions of messages/sec throughput, which degrades under high load without partitioning.
Synchronous vs. Asynchronous Real-Time Data Retrieval
The choice between synchronous and asynchronous methods depends on determinism, resource utilization, and use-case constraints. Synchronous retrieval (e.g., REST polling, gRPC) fetches data on-demand but introduces jitter (variable delay) and blocking behavior, making it unsuitable for high-frequency updates. Asynchronous methods (e.g., WebSockets, Kafka consumers) push data to clients, reducing latency but requiring stateful consumers to handle backpressure.Comparison Table: Synchronous vs. Asynchronous Methods
| Criteria | Synchronous (REST/gRPC) | Asynchronous (WebSockets/Kafka) |
|---|---|---|
| Latency | High (round-trip delay per request) | Low (push-based, near-instantaneous updates) |
| Resource Efficiency | Poor (idle connections consume bandwidth) | High (persistent connections, batching) |
| Scalability | Limited by connection overhead | Scales via pub/sub or partitioned logs |
| Use Cases | Low-frequency queries (e.g., API responses) | High-frequency updates (e.g., live dashboards) |
| Fault Tolerance | Retries on failure (increases latency) | Built-in retry/acknowledgment mechanisms |
| State Management | Stateless (each request is independent) | Stateful (consumers track offsets/positions) |
Hardware and Software Requirements for Real-Time Systems
Real-time systems demand low-latency hardware, optimized software stacks, and edge computing to minimize data travel distance. Hardware components include:Software requirements focus on minimizing serialization/deserialization overhead and leveraging kernel bypass:
Edge Computing Impact:
Deploying processing near data sources (e.g., 5G-enabled cameras) reduces latency by 90%+ compared to cloud-based pipelines. Example: Autonomous vehicles rely on <50ms edge-to-cloud round-trip for obstacle detection.
Conceptual Design of a Real-Time Data Pipeline
A real-time pipeline consists of three layers: ingestion, processing, and delivery. Each layer must balance throughput, latency, and fault tolerance. Below is a component breakdown:1. Ingestion Layer:
2. Processing Layer:
3. Delivery Layer:
Conceptual Flow Diagram Description:
[Data Source] → [Ingestion (Kafka/MQTT)] → [Processing (Flink/Redis)]
↓
[State Store] ← [Checkpointing]
↓
[Delivery (gRPC/WebSocket)] → [Client Applications]
- Data Source: Emits events (e.g., stock ticks, sensor telemetry).
Identifying Bottlenecks in Real-Time Systems
Bottlenecks manifest as latency spikes, throughput drops, or packet loss, often traced to hardware, software, or architectural misconfigurations. Key metrics to monitor include:Common Bottlenecks and Mitigations:
-
Network Latency:
- Symptoms: High jitter in WebSocket connections, timeouts in gRPC calls.
- Solutions: Use RDMA for shared-memory clusters, CDN edge caching for global deploy
- Automatic synchronization via WebSocket connections.
- Fine-grained security rules for access control.
- Built-in offline support with automatic sync on reconnection.
- Event-based change notifications.
- Support for filtering and aggregation.
- Compatible with MongoDB Atlas and self-hosted deployments.
- Firebase: Uses Firebase Authentication (Google, OAuth, email/password).
- MongoDB: Supports SCRAM, x.509, and LDAP for authentication.
- Firebase: Last-write-wins by default, with optional transaction support.
- MongoDB: Uses version vectors or application-level logic to resolve conflicts.
- Partitioned logs for horizontal scaling.
- Persistent storage with configurable retention.
- Support for exactly-once semantics.
- Open-Source:
- Apache Kafka – Distributed event streaming platform with high throughput (1M+ messages/sec per broker) and retention policies for replayability. Ideal for log aggregation, real-time analytics, and microservices.
- RabbitMQ – Lightweight broker supporting multiple protocols (AMQP, MQTT, STOMP) with clustering for high availability. Suitable for small-to-medium-scale applications requiring simplicity.
- NATS – Ultra-low-latency messaging system (sub-millisecond) with a focus on performance and minimal overhead. Used in cloud-native and edge computing scenarios.
- Redis Streams – In-memory pub/sub with append-only durability, integrated with Redis’ data structures for hybrid real-time and batch processing.
- Commercial:
- AWS Kinesis – Managed service for real-time data streaming with auto-scaling and serverless ingestion (Kinesis Data Streams) or analytics (Kinesis Data Analytics). Pricing scales with throughput and storage.
- Google Pub/Sub – Fully managed pub/sub with global load balancing and exactly-once delivery semantics. Integrates natively with BigQuery and Dataflow for analytics pipelines.
- Solace PubSub+ – Enterprise-grade broker supporting MQTT, AMQP, and REST, with features like message prioritization and multi-protocol routing.
- Open-Source:
- InfluxDB – Purpose-built for metrics and events with SQL-like query language (Flux) and downsampling for long-term retention. Supports InfluxDB Cloud and self-hosted deployments.
- TimescaleDB – PostgreSQL extension with hypertables for partitioning time-series data. Enables complex queries and joins with relational databases.
- Prometheus – Pull-based monitoring system with a focus on alerting and metrics collection. Often paired with Grafana for visualization.
- Commercial:
- Amazon Timestream – Serverless TSDB with automatic scaling and SQL-like queries. Optimized for IoT and operational metrics with millisecond latency.
- Druid – Columnar storage for real-time OLAP queries, supporting aggregations and time-based filtering. Used by Airbnb and Lyft for large-scale analytics.
- QuestDB – High-performance TSDB with SQL support and SIMD optimizations for ingestion rates exceeding 100K rows/sec.
- Open-Source/DIY:
- Cloudflare Workers – Serverless edge functions to proxy or transform real-time data streams (e.g., WebSocket relay) with global low-latency routing.
- Varnish Cache – HTTP reverse proxy with Lua scripting for custom real-time data caching logic.
- Commercial:
- Cloudflare Stream – Supports adaptive bitrate streaming and WebSocket connections for live video/audio with CDN acceleration.
- Fastly – Real-time compute at the edge with VCL (Varnish Configuration Language) for dynamic data processing.
- Akamai EdgeWorkers – Lua-based edge logic to modify or route real-time API responses with sub-100ms latency.
- Open-Source:
- Yjs – Framework for collaborative editing with CRDTs, used in tools like Etherpad and HackMD for real-time text synchronization.
- Firepad – Firebase-backed collaborative editor with OT for conflict resolution.
- Commercial:
- Slack – Uses a pub/sub model with WebSocket connections for message delivery, complemented by a distributed event bus for app integrations.
- Notion – Implements a hybrid OT/CRDT approach for real-time block-level editing, with differential synchronization to minimize bandwidth.
- Figma – Leverages WebSockets and a custom reconciliation algorithm to handle concurrent design edits across teams.
- Prometheus server collecting metrics (e.g., from Node Exporter, Kafka, or custom applications).
- Grafana instance with data source configured to Prometheus.
- Alertmanager for notification routing (email, Slack, PagerDuty).
-
Data Source Setup:
Add Prometheus as a data source in Grafana:URL:
Verify connectivity by running a test query (e.g.,http://prometheus-server:9090Access: Server (default)
HTTP Method: GET
upmetric). -
Dashboard Creation:
Create a new dashboard and add panels for key metrics. Example panels for a Kafka cluster:- Broker Health: Query
kafka_server_brokersfor broker count andkafka_server_upfor availability. - Throughput: Use
kafka_server_producer_request_rateandkafka_server_consumer_request_ratewith time series visualization. - Latency: Plot
kafka_network_request_latency_avgwith a threshold line at 500ms.
- Broker Health: Query
-
Alerting Rules:
Define alert rules in Prometheus (e.g.,prometheus.yml) and link them to Grafana:groups:
- name: kafka-alerts
rules:
- alert: HighProducerLatency
expr: rate(kafka_network_request_latency_avg{job="kafka"}[5m]) > 0.5
Security and Compliance in Real-Time Systems
Real-time data systems demand stringent security and compliance frameworks to mitigate risks associated with high-velocity data transmission, unauthorized access, and regulatory violations. Unlike batch-processing systems, real-time environments expose vulnerabilities such as latency-induced gaps in authentication, exposure to distributed denial-of-service (DDoS) attacks, and compliance challenges tied to instantaneous data handling. This section examines critical security measures—including encryption, authentication protocols, and rate limiting—as well as compliance checklists for frameworks like GDPR and HIPAA. Additionally, it explores the implementation of zero-trust architectures and analyzes real-world breaches to extract actionable lessons for system design. Regulatory obligations vary by industry, requiring tailored approaches for sectors such as finance (e.g., SEC real-time reporting) and healthcare (e.g., HL7 FHIR standards).
Critical Security Measures for Real-Time Systems
Real-time systems prioritize confidentiality, integrity, and availability (CIA triad) while operating under constraints like low latency and high throughput. Security measures must align with these operational demands without introducing performance bottlenecks. Below are foundational techniques categorized by their role in securing data in transit, at rest, and during processing.End-to-End Encryption (E2EE) and Data Protection
End-to-end encryption ensures that data remains unreadable during transmission and storage, even if intercepted. In real-time systems, TLS 1.3 is the preferred protocol for securing HTTP/HTTPS traffic due to its reduced latency (via session resumption and 0-RTT handshakes) and resistance to downgrade attacks. For internal communications (e.g., microservices), mutual TLS (mTLS) enforces authentication at both client and server levels, preventing man-in-the-middle (MITM) attacks. Data at rest should leverage AES-256 or ChaCha20-Poly1305 for encryption, with keys managed via Hardware Security Modules (HSMs) or cloud-based Key Management Services (KMS) like AWS KMS or Azure Key Vault.
Best Practice for Real-Time Encryption:
Authentication and Authorization: JWT/OAuth2 in Real-Time
Use TLS 1.3 for external APIs and mTLS for internal service-to-service communication. Rotate encryption keys automatically (e.g., every 24–72 hours) and store them in HSMs to prevent cryptographic backdoors.
JSON Web Tokens (JWT) and OAuth2 are widely adopted for real-time authentication due to their stateless nature and low overhead. However, their implementation must account for real-time constraints:
- JWT: Use short-lived access tokens (e.g., 5–15 minutes) with refresh tokens stored server-side to avoid replay attacks. Employ HMAC-SHA256 or RS256 for signing to prevent token forgery.
- OAuth2: Deploy the Authorization Code Flow with PKCE for public clients (e.g., mobile apps) to mitigate authorization code interception. For machine-to-machine (M2M) communication, use client credentials flow with mTLS for mutual authentication.
- Rate Limiting and Abuse Prevention: Real-time APIs are prime targets for brute-force attacks or scraping. Implement token bucket or leaky bucket algorithms to enforce request limits (e.g., 1000 requests/minute per token). Combine with IP reputation filtering and behavioral analysis (e.g., detecting sudden spikes in requests from a single endpoint).
OAuth2 Security Considerations for Real-Time:
Avoid long-lived refresh tokens; instead, use short-lived refresh tokens (e.g., 1 hour) with offline access revocation. Log all OAuth2 flows for audit purposes, especially token revocations.Compliance Checklist for Real-Time Data Access
Compliance in real-time systems extends beyond data protection to encompass data residency, consent management, and auditability. Regulatory frameworks like GDPR (EU), HIPAA (US healthcare), and SEC Rule 17a-4 (US finance) impose specific obligations that conflict with real-time processing requirements (e.g., "right to erasure" vs. instantaneous data replication). The following checklist aligns technical controls with common compliance mandates:Data Residency and Sovereignty
- Requirement: Ensure data storage and processing comply with regional laws (e.g., GDPR’s "data localization" clauses, China’s PII Protection Regulation).
- Implementation:
- Deploy geo-fenced databases (e.g., AWS Global Tables with residency rules) to restrict data movement across borders.
- Use data masking for cross-border transfers (e.g., anonymizing PII fields in real-time analytics).
- Maintain an inventory of data flows with automated alerts for unauthorized transfers (e.g., via AWS Config or Google Cloud Security Command Center).
Audit Logs and Immutable Records
- Requirement: GDPR (Article 30) and HIPAA (164.312) mandate audit trails for data access, modification, and deletion.
- Implementation:
- Enable immutable logging (e.g., AWS CloudTrail Lake, Azure Monitor with write-once-read-many storage).
- Log who accessed what, when, and from where, including failed attempts (e.g., using SIEM tools like Splunk or Datadog).
- Retain logs for minimum 6 years (GDPR) or 6 years post-deletion (HIPAA), with tamper-evident storage (e.g., blockchain-based logs for critical systems).
User Consent and Data Minimization
- Requirement: GDPR’s Article 7 (consent) and Article 5 (data minimization) require explicit, granular consent for real-time data processing.
- Implementation:
- Implement real-time consent management platforms (e.g., OneTrust, TrustArc) to track and revoke consent dynamically.
- Use purpose-binding in data models to restrict processing to declared use cases (e.g., "only for fraud detection").
- Provide opt-out mechanisms for real-time tracking (e.g., via header-based preferences like `DNT: 1`).
GDPR Right to Erasure in Real-Time:
Real-time systems must support instantaneous deletion of user data across all replicas (e.g., via distributed transaction protocols like Saga pattern). Document the deletion latency (e.g., "data erased within 500ms") in privacy policies.Zero-Trust Security Model for Real-Time APIs
The zero-trust architecture (ZTA) assumes breach and verifies every request, even from internal systems. For real-time APIs, this translates to continuous authentication, least-privilege access, and micro-segmentation. Below is a step-by-step implementation framework:1. Mutual TLS (mTLS) for Service Authentication
- Objective: Authenticate both client and server in real-time API calls.
- Implementation:
- Issue short-lived certificates (e.g., 1-hour validity) via Certificate Authorities (CAs) like Vault by HashiCorp or AWS Private CA.
- Enforce mTLS at the API gateway (e.g., Kong, Apigee) or service mesh (e.g., Istio, Linkerd).
- Use certificate pinning to prevent MITM attacks on internal traffic.
2. API Gateways with Policy Enforcement
- Objective: Centralize authentication, rate limiting, and logging.
- Implementation:
- Deploy API gateways (e.g., Amazon API Gateway, Kong) with:
- JWT validation (e.g., using Auth0 or Okta).
- Attribute-Based Access Control (ABAC) to enforce dynamic policies (e.g., "only allow `read:orders` for users in `role:admin`").
- Request/response transformation to sanitize inputs (e.g., SQL injection prevention).
- Integrate with SIEM tools for real-time anomaly detection (e.g., Splunk UBA).
3. Micro-Segmentation and Service Mesh
- Objective: Isolate real-time services to limit lateral movement.
- Implementation:
- Use service meshes (e.g., Istio) to enforce network policies between microservices.
- Implement mTLS between pods in Kubernetes clusters (e.g., via cert-manager).
- Apply pod-level firewalls (e.g., Calico) to restrict traffic between services.
4. Continuous Authentication and Behavioral Analysis
- Objective: Detect and respond to anomalies in real-time.
- Implementation:
- Deploy continuous authentication (e.g., behavioral biometrics via BioCatch or TypingDNA).
- Use UEBA (User and Entity Behavior Analytics) to flag deviations (e.g
Optimizing Performance for Real-Time Data Access
Real-time systems demand sub-millisecond response times, necessitating architectural optimizations to mitigate latency and ensure scalability under high-throughput conditions. Performance bottlenecks in such systems often arise from inefficient data retrieval, network overhead, or suboptimal resource allocation. Techniques like edge caching, connection pooling, and protocol-level optimizations directly address these challenges by reducing round-trip times, minimizing serialization overhead, and dynamically adapting to workload fluctuations. This section explores actionable strategies to achieve low-latency, high-throughput real-time data access, including empirical methods for benchmarking and stress-testing under simulated production loads.
Techniques for Reducing Latency in Real-Time Systems
Latency in real-time systems stems from network propagation delays, processing overhead, and inefficient data retrieval mechanisms. Mitigating these delays requires a multi-layered approach targeting both infrastructure and application logic.Edge Caching and CDN Leveraging
Edge caching reduces latency by storing frequently accessed data closer to end-users, leveraging Content Delivery Networks (CDNs) to distribute cached responses across geographically dispersed edge locations. For real-time APIs, CDNs like Cloudflare or Fastly can cache static payloads (e.g., configuration metadata, reference datasets) while bypassing origin servers for dynamic requests.Optimal edge caching strategies balance cache hit ratios with stale data risks, often employing time-to-live (TTL) policies tied to data volatility (e.g., 100ms TTL for stock tickers vs. 5s for weather updates).
Connection Pooling and Persistent Connections
Reusing TCP connections via connection pooling (e.g., HTTP keep-alive, WebSocket long-polling) eliminates the handshake overhead (TLS negotiation, SYN/ACK cycles) inherent in short-lived connections. For databases, connection pools (e.g., HikariCP for Java, PgBouncer for PostgreSQL) maintain a pool of pre-authenticated connections, reducing per-request latency by 30–70%.Connection pools should dynamically scale based on request queues, with idle connections terminated after inactivity thresholds (e.g., 30s) to prevent resource exhaustion.
Geographic Proximity and Anycast Routing
Real-time systems benefit from routing traffic to the nearest data center or edge node using Anycast DNS (e.g., Google’s Global Load Balancer). This reduces hop counts and mitigates cross-continental latency. For example, a financial trading platform routing orders to Frankfurt (10ms p99 latency) instead of Singapore (150ms) gains a critical advantage in high-frequency trading (HFT).
Load Testing Real-Time APIs with High-Frequency Requests
Simulating production-scale loads validates real-time API resilience under extreme conditions, exposing bottlenecks in throughput, concurrency, or backend saturation. Tools like Locust and JMeter provide programmable, distributed load generation with real-time metrics.Selecting Load Testing Tools
- Locust: Python-based, scriptable with user-defined behaviors (e.g., WebSocket message bursts), ideal for simulating interactive real-time workloads (e.g., chat applications).
- JMeter: Supports protocol-level testing (HTTP/2, WebSockets, gRPC) and integrates with plugins for custom metrics (e.g., WebSocket latency percentiles).
- k6: Lightweight, developer-friendly, and optimized for cloud-native testing with built-in Prometheus metrics.
Simulating High-Frequency Requests
To model real-time scenarios (e.g., IoT telemetry, live sports scores), configure tests to:
1. Vary request rates exponentially (e.g., 100 RPS → 10,000 RPS over 5 minutes) to identify breaking points.
2. Introduce think times between requests to simulate human-like or device-driven pacing (e.g., 50ms delays for sensor data).
3. Use weighted distributions for request types (e.g., 70% GET, 20% POST, 10% WebSocket messages).For WebSocket APIs, test both message throughput (messages/sec) and connection churn (connections/sec) to stress WebSocket servers like Socket.io or Pusher.
Key Metrics to Monitor
- Latency percentiles (p50, p95, p99) to detect tail latency spikes.
- Error rates (HTTP 5xx, WebSocket disconnections) under load.
- Throughput (requests/sec, messages/sec) at saturation.
- Resource utilization (CPU, memory, network I/O) to correlate with performance degradation.
Example Locust Script for Real-Time API Testing
from locust import HttpUser, task, between
class RealTimeUser(HttpUser):
wait_time = between(0.05, 0.2) # Simulate 50ms–200ms think time
@task(3)
def fetch_stream(self):
self.client.get("/stream", headers={"Accept": "text/event-stream"})
@task(1)
def send_event(self):
self.client.post("/events", json={"data": "update"})
Data Compression and Binary Protocols for Throughput Optimization
Text-based protocols (JSON, XML) introduce serialization overhead, increasing payload sizes and network latency. Binary formats and compression reduce payloads by 50–90%, critical for high-frequency real-time data (e.g., stock quotes, sensor telemetry).Binary Protocols and Serialization
- Protocol Buffers (protobuf): Google’s language-neutral binary format with schema evolution support. Reduces JSON payloads by 3–10x (e.g., 1KB JSON → 100B protobuf).
- MessagePack: Binary JSON alternative with 50–90% smaller sizes than JSON, widely used in IoT (e.g., MQTT payloads).
- FlatBuffers: Zero-copy serialization for high-performance applications (e.g., game engines, AR/VR).
Compression TechniquesBinary protocols require schema validation at both ends; tools like `protoc` (protobuf) or `msgpack-cli` automate serialization/deserialization.
- gzip/deflate: Reduces text-based payloads (e.g., JSON) by 60–80%. Enabled via HTTP `Content-Encoding: gzip`.
- Brotli: Modern compression (20–30% better than gzip) for static assets or metadata-heavy APIs.
- Zstandard (zstd): Balances speed and ratio (3–4x faster than gzip) for dynamic data (e.g., logs, telemetry).
Protocol-Level Optimizations
- HTTP/2 and HTTP/3: Multiplexing reduces head-of-line blocking; QUIC (HTTP/3) further cuts latency via UDP-based connections.
- gRPC: Uses HTTP/2 + protobuf for low-latency RPC (e.g., 5ms p99 for cross-service calls in Kubernetes).
- WebSocket Extensions: Frame compression (e.g., `permessage-deflate`) reduces WebSocket payloads by 50–70%.
Benchmarking Compression Overhead
Format Avg. Size (B) Deserialization (µs) Use Case JSON 1,000 500 Human-readable APIs Protobuf 100 50 High-frequency RPC MessagePack 150 30 IoT/Edge devices FlatBuffers 80 20 Real-time rendering Handling Backpressure in Real-Time Streams
Backpressure occurs when producers overwhelm consumers in real-time pipelines (e.g., Kafka topics, WebSocket streams), leading to buffer overflows or dropped messages. Strategies include dynamic scaling, buffer management, and adaptive throttling.Buffer Management Techniques
- Fixed-Sized Buffers: Pre-allocate memory pools (e.g., 1MB buffers for 10,000 messages) to avoid GC pauses.
- Ring Buffers: Circular buffers (e.g., LMAX Disruptor) enable lock-free, high-throughput enqueuing/dequeuing.
- Priority Queues: Use weighted fair queuing (WFQ) to prioritize critical messages (e.g., market orders over analytics logs).
Dynamic Scaling Strategies
- Horizontal Scaling: Auto-scale consumers (e.g., Kubernetes HPA) based on queue depth (e.g., scale to 5 pods if Kafka lag > 10,000 messages).
- Vertical Scaling: Increase consumer batch sizes (e.g., from 100 → 1,000 messages/batch) to amortize processing overhead.
- Backpressure Indicators: Expose metrics like `queue_length` or `processing_latency` to trigger scaling (e.g., via Prometheus alerts).
Adaptive Throttling
- Token Buckets: Limit request rates (e.g., 1,0
Mastering real-time data access demands a blend of technical expertise, strategic planning, and continuous optimization. Whether deploying a live analytics dashboard, integrating IoT sensors, or adhering to financial compliance standards, the principles outlined here provide a structured approach to overcoming common pitfalls. By leveraging tools like Kafka for stream processing, Grafana for visualization, or serverless architectures for scalability, organizations can future-proof their systems against evolving demands. The key lies in balancing speed with security, scalability with cost-efficiency, and innovation with regulatory adherence—a challenge that this guide addresses through practical frameworks and real-world examples.
As real-time systems become the backbone of modern applications, the ability to design, deploy, and maintain them effectively will define competitive advantage. This guide serves as both a reference and a catalyst for action, empowering teams to transform raw data into actionable insights with precision and confidence. The journey from conceptual understanding to operational excellence begins with the insights shared here, ensuring that every system built today is resilient, performant, and future-ready.
Methods for Real-Time Data Retrieval
Real-time data retrieval enables systems to process and act on data as it is generated, eliminating latency and improving responsiveness. This section explores the primary methods for accessing real-time data, including API-based approaches, database synchronization techniques, and stream processing frameworks. Each method varies in complexity, scalability, and use-case applicability, requiring careful evaluation based on architectural constraints and performance requirements.API-Based Real-Time Data Access Methods
APIs serve as the backbone for real-time data exchange, offering low-latency communication between clients and servers. The choice of protocol dictates performance, reliability, and scalability. Below are the most widely adopted real-time API methods, along with implementation examples.RESTful APIs with Polling
Traditional REST APIs rely on HTTP requests, but real-time behavior is emulated via frequent polling (e.g., every 5 seconds). While simple to implement, this approach introduces unnecessary network overhead and latency. Polling is suitable for low-frequency updates but inefficient for high-velocity data.
WebSockets
WebSockets provide full-duplex, persistent connections between clients and servers, enabling bidirectional communication with minimal latency. They are ideal for applications requiring interactive updates, such as chat applications, live dashboards, or collaborative tools.
A WebSocket connection begins with an HTTP handshake, upgrading to the WebSocket protocol (ws:// or wss://). Once established, data is exchanged over a single TCP connection without repeated HTTP overhead.Implementation Example (Node.js with `ws` library):
// Server-side (Node.js)
const WebSocket = require('ws');
const wss = new WebSocket.Server({ port: 8080 });
wss.on('connection', (ws) => {
ws.on('message', (message) => {
console.log(`Received: ${message}`);
ws.send(`Echo: ${message}`); // Simulate real-time response
});
});
// Client-side (Browser JavaScript)
const socket = new WebSocket('ws://localhost:8080');
socket.onmessage = (event) => {
console.log(`Server: ${event.data}`);
};
socket.send('Hello Server!');
Server-Sent Events (SSE)
SSE is a server-to-client unidirectional protocol built on HTTP, allowing servers to push updates to clients incrementally. It is lightweight and widely supported in modern browsers, making it suitable for live notifications, stock tickers, or social media feeds.
SSE uses standard HTTP connections, ensuring compatibility with firewalls and proxies. However, it lacks client-to-server messaging, limiting interactivity.Implementation Example (Node.js with `express`):
// Server-side
const express = require('express');
const app = express();
app.get('/events', (req, res) => {
res.setHeader('Content-Type', 'text/event-stream');
res.write('data: Initial message\n\n');
const interval = setInterval(() => {
res.write(`data: Updated at ${new Date().toISOString()}\n\n`);
}, 2000);
req.on('close', () => clearInterval(interval));
});
app.listen(3000);
// Client-side (Browser JavaScript)
const eventSource = new EventSource('http://localhost:3000/events');
eventSource.onmessage = (e) => {
console.log(`Event: ${e.data}`);
};
GraphQL Subscriptions
GraphQL subscriptions extend GraphQL’s query capabilities by enabling real-time updates via WebSockets or SSE. Clients subscribe to specific data changes, reducing over-fetching and improving efficiency. This method is ideal for complex, graph-structured data (e.g., social networks, IoT telemetry).
GraphQL subscriptions require a subscription server (e.g., Apollo Server, Hasura) to manage persistent connections and publish updates to subscribed clients.Implementation Example (Apollo Server with WebSockets):
// Server-side (Apollo Server)
const { ApolloServer, gql } = require('apollo-server');
const pubsub = new PubSub();
const typeDefs = gql`
type Subscription {
messageAdded: String!
}
type Query { _: Boolean }
`;
const resolvers = {
Subscription: {
messageAdded: {
subscribe: () => pubsub.asyncIterator(['MESSAGE_ADDED']),
},
},
};
const server = new ApolloServer({ typeDefs, resolvers });
server.listen().then(({ url, subscriptionsUrl }) => {
console.log(`🚀 Server ready at ${url}`);
console.log(`🚀 Subscriptions ready at ${subscriptionsUrl}`);
});
// Client-side (Apollo Client)
import { ApolloClient, InMemoryCache, split, HttpLink } from '@apollo/client';
import { WebSocketLink } from '@apollo/client/link/ws';
import { getMainDefinition } from '@apollo/client/utilities';
const httpLink = new HttpLink({ uri: 'http://localhost:4000' });
const wsLink = new WebSocketLink({
uri: 'ws://localhost:4000/graphql',
options: { reconnect: true },
});
const splitLink = split(
({ query }) => {
const definition = getMainDefinition(query);
return definition.kind === 'OperationDefinition' &&
definition.operation === 'subscription';
},
wsLink,
httpLink,
);
const client = new ApolloClient({
link: splitLink,
cache: new InMemoryCache(),
});
// Subscribe to updates
client.subscribe({
query: gql`
subscription {
messageAdded
}
`,
}).subscribe({
next(data) {
console.log('New message:', data.data.messageAdded);
},
});
Setting Up Real-Time Databases for Live Synchronization
Real-time databases automatically propagate changes to connected clients, eliminating the need for manual polling. These systems are optimized for low-latency updates and often include built-in conflict resolution and authentication mechanisms.Firebase Realtime Database
Firebase provides a NoSQL cloud database with real-time synchronization capabilities. Data is synchronized across all connected clients instantly, and Firebase handles offline persistence and conflict resolution.
Key Features:
Implementation Example (JavaScript Client):
import { initializeApp } from 'firebase/app';
import { getDatabase, ref, onValue } from 'firebase/database';
const firebaseConfig = { / Your Firebase config / };
const app = initializeApp(firebaseConfig);
const db = getDatabase(app);
const messagesRef = ref(db, 'messages');
onValue(messagesRef, (snapshot) => {
const messages = snapshot.val();
console.log('Updated messages:', messages);
});
MongoDB Change Streams
MongoDB Change Streams allow applications to monitor changes to collections in real time. This feature is useful for building reactive systems, such as audit logs, notifications, or event-driven architectures.
Key Features:
Implementation Example (Node.js with MongoDB Driver):
const { MongoClient } = require('mongodb');
async function watchChanges() {
const client = new MongoClient('mongodb://localhost:27017');
await client.connect();
const db = client.db('test');
const collection = db.collection('events');
const changeStream = collection.watch();
changeStream.on('change', (change) => {
console.log('Change detected:', change);
});
}
watchChanges();
Authentication and Conflict Resolution
Real-time databases require robust authentication to prevent unauthorized access. Common methods include:
Conflict resolution strategies vary by database:
Integrating Real-Time Analytics Tools
Real-time analytics tools process data streams as they arrive, enabling instantaneous insights. Integration with existing data sources requires careful consideration of scalability, latency, and fault tolerance.Apache Kafka
Kafka is a distributed event streaming platform designed for high-throughput, low-latency data pipelines. It decouples producers and consumers, allowing scalable real-time processing.
Key Features:
Implementation Example (Producer and Consumer in Python):
# Producer
from kafka import KafkaProducer
import json
producer = KafkaProducer(
bootstrap_servers=['localhost:9092'],
value_serializer=lambda v: json.dumps(v).encode('utf-8')
)
producer.send('real-time-data', {'event': 'click', 'value': 100})
producer.flush()
# Consumer
from kafka import KafkaConsumer
import json
consumer = KafkaConsumer(
'real-time-data',
bootstrap_servers

Tools and Platforms for Real-Time Data Access
Real-time data access relies on specialized tools and platforms designed to ingest, process, and distribute data with minimal latency. These solutions span messaging systems, databases, serverless architectures, and visualization tools, each optimized for specific use cases—from IoT telemetry to collaborative workflows. Selecting the right combination of tools ensures scalability, fault tolerance, and seamless integration with existing infrastructure. Below is a structured breakdown of key categories, configuration examples, and architectural considerations for deploying real-time systems.Curated List of Open-Source and Commercial Tools
Real-time data access tools are categorized by their primary function: data ingestion, processing, storage, distribution, and visualization. The following lists highlight widely adopted solutions, balancing performance, cost, and ecosystem support.Messaging Brokers (Pub/Sub Systems)
Messaging brokers facilitate asynchronous communication between distributed systems, enabling event-driven architectures. They are critical for decoupling producers and consumers while ensuring reliability through persistence and acknowledgment mechanisms.
TSDBs optimize for storing and querying time-ordered data, such as metrics, events, or sensor readings. They employ compression techniques and indexing strategies to handle high write/read volumes with low latency.
CDNs reduce latency for globally distributed applications by caching and delivering data closer to end-users. While traditionally used for static assets, modern CDNs support dynamic content and WebSocket-based real-time updates.
These platforms handle concurrent user interactions through operational transformation (OT) or conflict-free replicated data types (CRDTs), ensuring consistency across devices without central coordination.
Configuring a Real-Time Monitoring Dashboard
Real-time dashboards (e.g., Grafana, Kibana) aggregate data from multiple sources and present it with interactive controls, thresholds, and alerts. Below are steps to configure a live monitoring setup using Grafana with Prometheus and Alertmanager.Prerequisites:
Step-by-Step Configuration:
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of ir.msu.ac.zw.