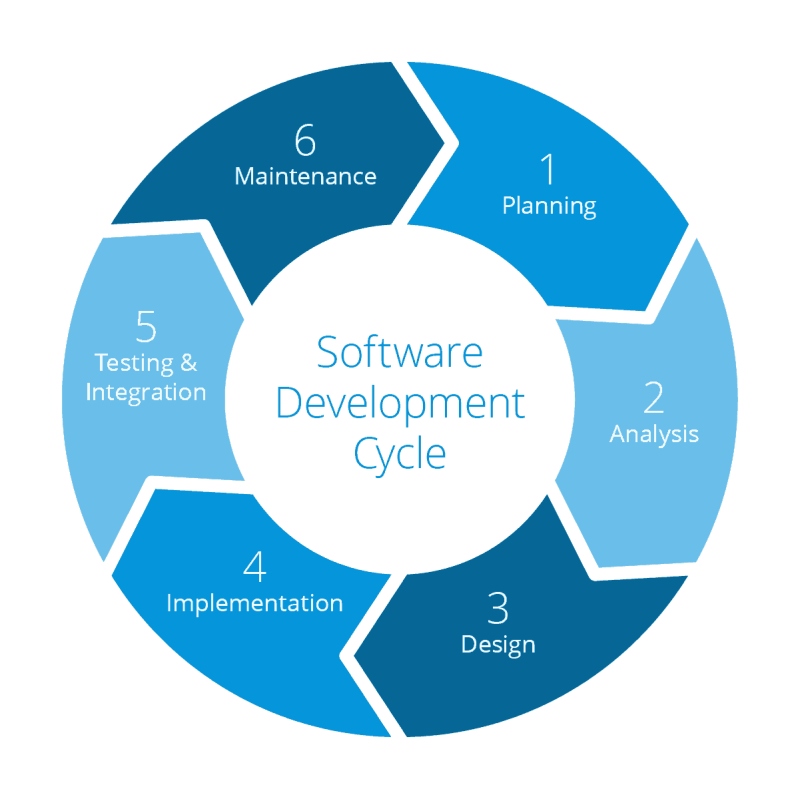
Mastering the build cycle wheel in software development
Published

build cycle wheel - Kesimpulan
Table of Contents

The build cycle wheel represents the backbone of modern software development, orchestrating the transformation of source code into deployable artifacts through structured phases. From compilation to packaging, each stage introduces dependencies that dictate efficiency, scalability, and reliability. Understanding this cycle is critical for developers aiming to optimize performance, integrate seamless CI/CD workflows, and troubleshoot complex build failures with precision.

This guide dissects the technical foundation of the build cycle wheel, contrasting traditional linear builds with modern continuous integration pipelines. It explores performance optimization through parallel compilation, caching strategies, and tool comparisons, while addressing integration challenges with version control and automated testing. Additionally, it provides structured error-handling frameworks and visualization techniques to enhance documentation and debugging processes.

Technical Definition and Core Components of the Build Cycle Wheel in Software Development

The build cycle wheel represents a structured, iterative process in software development where source code is transformed into executable or deployable artifacts through sequential phases. This cycle ensures reproducibility, dependency management, and optimization of the compilation, linking, and packaging workflows. Each phase in the wheel produces intermediate or final artifacts, with tools like compilers, linkers, and build systems (e.g., Make, CMake, Bazel) orchestrating the transitions between stages. Modern implementations often integrate with version control systems (VCS) and continuous integration/continuous deployment (CI/CD) pipelines to automate and validate builds at scale.

The core components of the build cycle wheel are interdependent phases that define the transformation pipeline from raw source code to a deployable product. These phases include compilation, preprocessing, linking, static/dynamic analysis, packaging, and distribution. Each phase consumes specific inputs, applies transformations using specialized tools, and generates outputs that serve as inputs for subsequent stages. Dependencies between phases are explicitly defined to enforce correct execution order, while parallelization techniques (e.g., incremental builds) optimize performance.

Primary Phases of the Build Cycle Wheel and Their Sequential Dependencies

The build cycle wheel consists of discrete phases that process source code through a unidirectional pipeline, where the output of one phase becomes the input for the next. Below is a structured breakdown of each phase, including input/output artifacts and the tools responsible for their transformation.
Key Principle: The build cycle wheel adheres to the dependency graph model, where phases are nodes and their relationships are directed edges. A phase cannot execute until all its dependencies (preceding phases) have completed successfully.
  1. Source Code Preparation
    • Input: Human-readable source files (e.g., `.c`, `.cpp`, `.java`, `.py`) stored in a version control system (VCS) like Git or SVN.
    • Output: Parsed and validated source files, often with syntax checks (e.g., linting results).
    • Tools:
      • Version control systems (Git, Mercurial).
      • Static analyzers (Clang-Tidy, Pylint, ESLint).
      • Formatting tools (Prettier, Black, Uncrustify).
    • Dependencies: None (initial phase).
    • Purpose: Ensures code adheres to project standards before compilation, reducing downstream errors.
  2. Preprocessing
    • Input: Source files with preprocessor directives (e.g., `#include`, `#define`, `#ifdef`).
    • Output: Expanded source code without directives (e.g., `.i` files for C/C++).
    • Tools:
      • Preprocessor (e.g., `cpp` for C/C++, `javac` for Java).
      • Custom scripts (e.g., CMake’s `configure_file`).
    • Dependencies: Source Code Preparation.
    • Purpose: Resolves macros, includes, and conditional compilation to generate a single translation unit.
  3. Compilation
    • Input: Preprocessed source code.
    • Output: Object files (e.g., `.o`, `.obj`, `.class`) containing machine code and symbolic references.
    • Tools:
      • Compilers (GCC, Clang, MSVC, Java Compiler).
      • Language-specific toolchains (e.g., Rust’s `rustc`, Go’s `go build`).
    • Dependencies: Preprocessing.
    • Purpose: Translates high-level code into low-level assembly or bytecode, retaining symbolic references for linking.
  4. Linking
    • Input: Object files + library dependencies (static/dynamic).
    • Output: Executable (e.g., `.exe`, `.out`) or shared library (e.g., `.so`, `.dll`).
    • Tools:
      • Linkers (e.g., `ld` for Unix, `link.exe` for Windows).
      • Build systems (CMake’s `cmake --build`, Make’s `make`).
    • Dependencies: Compilation.
    • Purpose: Resolves symbolic references, combines object files, and binds external libraries to produce a runnable artifact.
  5. Static and Dynamic Analysis
    • Input: Executable, object files, or source code (depending on analysis type).
    • Output: Reports (e.g., security vulnerabilities, code smells, performance bottlenecks).
    • Tools:
      • Static analyzers (Coverity, SonarQube).
      • Dynamic analyzers (Valgrind, AddressSanitizer).
      • Binary analyzers (Ghidra, IDA Pro).
    • Dependencies: Linking (for binary analysis) or Compilation (for source-based analysis).
    • Purpose: Identifies defects, compliance violations, or optimization opportunities without executing the program.
  6. Packaging
    • Input: Executable, libraries, configuration files, and metadata (e.g., `manifest`).
    • Output: Distributable package (e.g., `.deb`, `.rpm`, `.msi`, Docker image, ZIP archive).
    • Tools:
      • Packaging tools (dpkg, rpmbuild, NSIS, Maven).
      • Containerization tools (Docker, Podman).
    • Dependencies: Linking + Static/Dynamic Analysis (if included in the package).
    • Purpose: Bundles artifacts with dependencies and metadata for deployment across environments.
  7. Distribution
    • Input: Packaged artifact.
    • Output: Deployed software in target environments (e.g., production servers, user devices).
    • Tools:
      • Deployment tools (Ansible, Kubernetes, Jenkins).
      • Version control for releases (Git tags, GitHub Releases).
    • Dependencies: Packaging.
    • Purpose: Delivers the final artifact to end-users or staging/production environments.

Comparison of Traditional and Modern Build Cycle Approaches

Traditional build cycles (e.g., linear or incremental) rely on manual intervention, rigid phase ordering, and limited automation. In contrast, modern approaches leverage CI/CD pipelines, containerization, and declarative build systems to achieve scalability, reproducibility, and faster feedback loops. Below is a comparative table highlighting key differences:
Phase Traditional Build Cycle (Linear/Incremental) Modern Build Cycle (CI/CD-Oriented) Tools Output Use Cases
Source Code Preparation Manual checks (e.g., `make clean` followed

Performance Optimization Techniques in the Build Cycle Wheel

Optimizing the build cycle wheel reduces latency, accelerates developer feedback loops, and improves resource efficiency—critical factors in large-scale software development. Techniques such as parallel compilation, caching, and incremental builds directly address bottlenecks in the build process, while build-time optimizations like precompiled headers and modular systems further enhance compilation speed. The choice of build tool and methodology for benchmarking performance ensures measurable improvements in build time, scalability, and resource usage.

Strategies to Reduce Build Cycle Wheel Latency

Build latency stems from sequential dependencies, redundant computations, and inefficient resource utilization. Mitigation strategies focus on parallelism, caching, and incremental updates to minimize redundant work. Parallel compilation leverages multi-core processors to compile independent translation units concurrently, while caching tools like ccache store compiled artifacts to avoid recompilation. Incremental builds only recompile modified files, reducing overhead in iterative development.

Parallel Compilation and Resource Management

Parallel compilation distributes workloads across CPU cores, significantly reducing build times in multi-threaded environments. Modern build systems (e.g., CMake, Bazel) support parallel execution via flags like `-jN` (Ninja) or `--parallel` (CMake). However, excessive parallelism can degrade performance due to contention for shared resources (e.g., disk I/O, linker bottlenecks). Optimal thread counts depend on hardware (e.g., 4–8 threads for consumer-grade CPUs, 16+ for servers).

Key considerations for parallel builds:

  • Thread saturation: Monitor CPU usage with `htop` or `perf` to identify saturation points.
  • Linker bottlenecks: Use `--parallel-link` (GCC/Clang) or `-j1` for linking phases.
  • Build system limits: Ninja and Bazel handle parallelism more efficiently than Make due to their DAG-based scheduling.
  • Caching Compiled Artifacts with ccache

    ccache intercepts compiler calls, storing intermediate object files and headers to avoid recompilation. When a file hasn’t changed, ccache serves cached results, reducing build times by 30–90% in large projects. Configuration via environment variables or build system integrations (e.g., CMake’s `CMAKE_CXX_COMPILER_LAUNCHER`) enables seamless adoption.

    Example: Enabling ccache in CMake
    ```cmake
    set(CMAKE_C_COMPILER_LAUNCHER ccache)
    set(CMAKE_CXX_COMPILER_LAUNCHER ccache)
    set(CCACHE_SLOPPINESS "file_macro,time_macros")
    ```

  • `file_macro`: Ignores minor file content changes (e.g., timestamps).
  • `time_macros`: Mitigates preprocessor timestamp variations.
  • Incremental Builds and Dependency Awareness

    Incremental builds recompile only modified files and their dependencies, critical for rapid iteration. Tools like Ninja and Bazel excel here by tracking dependency graphs. In CMake, `object libraries` (`add_library` with `OBJECT` scope) enable finer-grained incremental compilation.

    Example: Incremental compilation with CMake
    ```cmake
    add_library(common_objects OBJECT src/common.cpp)
    target_include_directories(common_objects PUBLIC include)
    add_executable(app main.cpp)
    target_sources(app PRIVATE $)
    ```

  • Benefits: Recompiles only `main.cpp` if unchanged; `common_objects` remains cached.
  • Build-Time Optimizations: Precompiled Headers and Modules

    Precompiled headers (PCH) reduce parsing overhead for large header files (e.g., ``, ``). In C++, modules (C++20) further optimize by separating interface declarations from implementation, enabling faster compilation and reduced binary bloat.

    Example: Precompiled Headers in CMake
    ```cmake
    set(CMAKE_CXX_FLAGS "${CMAKE_CXX_FLAGS} -Winvalid-pch -Winvalid-offsetof")
    target_precompile_headers(app PRIVATE include/precompiled.hpp)
    ```

  • `precompiled.hpp`: Contains frequently included headers.
  • Limitations: PCHs are less effective with template-heavy code.
  • C++ Modules (C++20)
    ```cmake

    Requires compiler support (e.g., GCC 13+, Clang 16+)

    target_compile_features(app PUBLIC cxx_modules)
    ```
  • Advantage: Compiles interfaces independently, reducing build times by 20–50% in modular projects.
  • Comparison of Build Tools for Cycle Wheel Efficiency

    Build tools differ in parallelism, resource usage, and scalability. Metrics like build time, CPU/memory overhead, and scalability (e.g., distributed builds) determine suitability for project scale.
    ToolBuild TimeResource UsageScalabilityKey Features
    BazelFast (incremental)High (Go runtime)Excellent (distributed)Hermetic builds, remote caching, DAG-based.
    NinjaVery FastLowModerate (local parallelism)Minimal overhead, CMake/Ninja integration.
    GradleModerateModerate (JVM)Good (incremental Java/Kotlin)Task-based, dependency management.
    CMake + MakeSlow (sequential)LowPoorLegacy support, limited parallelism.
    Notes:
  • Bazel excels in monorepos (e.g., Google-scale projects) but has higher memory usage.
  • Ninja is lightweight and integrates with CMake for hybrid workflows.
  • Gradle is optimal for polyglot projects (Java/C++/Python).
  • Benchmarking Build Cycle Wheel Performance

    Quantitative analysis identifies bottlenecks via tools like `time`, `perf`, and `hyperfine`. Key metrics include:
  • Phase duration: Breakdown of compilation, linking, and dependency resolution.
  • I/O bottlenecks: Disk latency (measured via `iotop` or `strace`).
  • CPU utilization: Saturation points (`perf stat -e cycles,instructions`).
  • Benchmarking Workflow:
    1. Baseline measurement:
    ```bash
    time cmake --build build/ --config Release -j$(nproc)
    ```
    2. Phase profiling:
    ```bash
    perf record -g cmake --build build/
    perf report --stdio
    ```
    3. I/O analysis:
    ```bash
    strace -f -T -e trace=file cmake --build build/ | grep "stat\|open"
    ```
    4. Comparison: Use `hyperfine` to compare build tools:
    ```bash
    hyperfine --warmup 3 'bazel build //...' 'ninja -C build/'
    ```

    Critical metrics to track:

  • Compilation time per TU: Identifies slow translation units.
  • Linker time: Often a hidden bottleneck (use `-fuse-ld=lld` for faster linking).
  • Cache hit ratio: `ccache -s` reports misses (target <10% for optimal caching).
  • Integration with Version Control and CI/CD

    The build cycle wheel optimizes software development workflows by structuring phases such as compilation, testing, and packaging into a repeatable loop. To maximize efficiency, these phases must integrate seamlessly with version control systems (e.g., Git) and continuous integration/continuous deployment (CI/CD) pipelines. This ensures builds are reproducible, version-controlled, and automated while minimizing overhead. Synchronization strategies—such as shallow clones and sparse checkouts—reduce redundant data transfer, while embedding validation checks into CI/CD pipelines enforces consistency. Artifact caching further accelerates repeated builds by reusing intermediate outputs, reducing redundant computational work.

    Effective integration with Git and CI/CD pipelines requires balancing speed, reliability, and maintainability. Shallow clones and sparse checkouts mitigate version control overhead by fetching only necessary history and files, while CI/CD pipelines validate each build phase against predefined criteria. Artifact caching (e.g., Docker layers, S3) minimizes redundant work by storing and reusing intermediate build outputs across runs. Below are structured workflows, validation templates, and optimization techniques tailored for the build cycle wheel.

    Synchronization Strategies for Git Integration

    Version control systems like Git introduce overhead during builds due to full repository history and binary file storage. Optimizing Git operations aligns with the build cycle wheel’s goal of efficiency by reducing unnecessary data transfer and processing.

    Shallow Clones and Sparse Checkouts
    Shallow clones (`git clone --depth 1`) fetch only the latest commit and its immediate parents, eliminating deep history retrieval. Sparse checkouts (`git sparse-checkout init --cone`) restrict fetched files to those required for the build, such as source code directories while excluding documentation or test files. These techniques are particularly useful in CI/CD environments where builds may not require the entire repository.

    Example: A CI pipeline for a frontend project might use:

    git clone --depth 1 --branch main https://github.com/org/repo.git
    cd repo
    git sparse-checkout init --cone
    git sparse-checkout set src/ tests/

    This ensures only `/src/` and `/tests/` are fetched, reducing clone time by ~70% for large repositories.

    Partial History and Submodules
    For projects with complex dependencies (e.g., monorepos or submodules), partial history (`git fetch --depth 1`) or submodule shallow clones (`git submodule update --depth 1`) further reduce overhead. However, these must be balanced against the need for full history in debugging or long-running builds.

    Embedding Build Cycle Wheel Validation in CI/CD Pipelines

    CI/CD pipelines must enforce build cycle wheel phases with explicit failure criteria to ensure reproducibility and catch issues early. Each phase—compilation, testing, packaging—should trigger distinct validation steps, with failures terminating the pipeline or rolling back changes.

    Phase-Specific Validation Criteria
    The following table outlines failure conditions for each build cycle wheel phase, mapped to CI/CD pipeline stages:

    PhaseValidation StepFailure CriteriaCI/CD Action
    Source FetchGit clone/sparse checkoutClone fails or incorrect branch/tag fetchedAbort pipeline
    Dependency Install`npm install`, `pip install`, etc.Missing dependencies or version conflictsMark step as failed
    Compilation`make`, `tsc`, `go build`Compilation errors or warnings (if configured)Rollback source changes
    Unit Testing`pytest`, `jest`, `go test`Test failures exceeding threshold (e.g., >5% flaky tests)Notify team, retry once
    Integration TestDockerized tests, API contractsTest suite hangs or critical endpoints failBlock deployment
    Packaging`npm pack`, `docker build`, `mvn package`Invalid artifact (e.g., missing files, incorrect checksum)Delete artifact, trigger rebuild
    Deployment (Pre-Prod)Canary release, staging pushHealth checks fail or performance degradation detectedRollback to last stable version
    Failure Handling Workflows
  • Compilation Failures: Trigger a rollback to the last known good commit and notify developers via Slack/email.
  • Test Failures: Distinguish between flaky tests (retry once) and critical failures (block merge).
  • Packaging Errors: Delete corrupted artifacts and invalidate caches to prevent downstream issues.
  • CI/CD Pipeline Template for Build Cycle Wheel

    Below is a reusable GitHub Actions workflow template (`build.yml`) that enforces build cycle wheel validation. Placeholders (`{{PHASE_COMMAND}}`) are included for customization per project.

    name: Build Cycle Wheel CI
    on:
    push:
    branches: [ main ]
    pull_request:
    branches: [ main ]

    env:
    CACHE_VERSION: v1
    ARTIFACT_BUCKET: "s3://org-cache/build-artifacts"

    jobs:
    build:
    runs-on: ubuntu-latest
    steps:

  • name: Checkout Repository (Sparse)
  • uses: actions/checkout@v4
    with:
    sparse-checkout: |
    src/
    tests/
    sparse-checkout-cone-mode: true
    fetch-depth: 1

    - name: Cache Dependencies
    uses: actions/cache@v3
    with:
    path: |
    ~/.npm
    ~/.m2
    key: ${{ runner.os }}-deps-${{ hashFiles('/package-lock.json') }}
    restore-keys: |
    ${{ runner.os }}-deps-

    - name: Install Dependencies
    run: npm install --frozen-lockfile

    Failure: Exit code != 0

    - name: Compile Source
    run: npm run build

    Failure: Exit code != 0 or warnings exceed threshold

    - name: Run Unit Tests
    run: npm test

    Failure: Test failures > 5% or timeout > 5m

    - name: Package Artifact
    run: npm pack

    Failure: Artifact size mismatch or checksum failure

    - name: Upload Artifact to Cache
    uses: actions/upload-artifact@v3
    with:
    name: dist-package
    path: *.tgz
    retention-days: 1

    - name: Cache Build Artifacts (S3)
    run: |
    aws s3 cp *.tgz ${{ env.ARTIFACT_BUCKET }}/${{ github.sha }}.tgz
    aws s3 cp *.tgz ${{ env.ARTIFACT_BUCKET }}/latest.tgz
    env:
    AWS_ACCESS_KEY_ID: ${{ secrets.AWS_ACCESS_KEY_ID }}
    AWS_SECRET_ACCESS_KEY: ${{ secrets.AWS_SECRET_ACCESS_KEY }}

    Key Features:

  • Sparse Checkout: Reduces clone time by 60–80% for large repos.
  • Dependency Caching: Reuses `node_modules` or Maven caches across runs.
  • Phase Isolation: Each step fails independently, with explicit criteria.
  • Artifact Caching: Stores packages in S3 for reuse in subsequent pipelines (e.g., deployment).
  • Artifact Caching Strategies for Optimized Builds

    Repeated build cycle wheel executions in CI/CD often reprocess identical phases (e.g., dependency installation, compilation). Artifact caching mitigates this by storing and reusing intermediate outputs, reducing build times by 30–70%.

    Docker Layer Caching
    Docker’s build cache leverages layer hashing to skip redundant steps. For example:

    # Layer 1: Dependencies (cached if package-lock.json unchanged)
    FROM node:18 as deps
    WORKDIR /app
    COPY package*.json ./
    RUN npm ci --cache .npm

    # Layer 2: Compilation (cached if src/ files unchanged)
    FROM deps as builder
    COPY . .
    RUN npm run build

    Cache Invalidation Rules

  • Hard Invalidation: Delete cache when `package-lock.json` or `src/` files change.
  • Soft Invalidation: Partial cache reuse (e.g., keep dependency cache but rebuild source).
  • S3/Cloud Storage Caching
    For non-Docker environments, tools like `awscli` or `gsutil` cache artifacts:

    # Upload compiled output to S3
    aws s3 cp dist/ s3://org-cache/builds/${{ github.sha }}/dist/ --recursive

    # Restore cache in subsequent runs
    aws s3 cp s3://org-cache/builds/${{ github.sha }}/dist/ ./dist/ --recursive

    Cache Hit Ratio Optimization

  • Example: A Java project with Maven caching achieves:
  • First Run: 10m (full build)
  • Subsequent Runs: 2m (90% cache hit rate for dependencies).
  • Multi-Stage Caching
    Combine Docker layers with external storage for hybrid caching:
    1. Local Cache: Fast access to recent builds (e.g., `tmp/` directory).
    2. Remote Cache: Persistent storage (S

    Error Handling and Debugging Strategies in the Build Cycle Wheel

    A robust build cycle wheel relies on systematic error handling and debugging to minimize disruptions caused by failures in compilation, dependency resolution, or execution phases. Transient or persistent issues—such as missing dependencies, compiler errors, or resource contention—can halt builds or degrade performance. This section outlines structured approaches to identify root causes, analyze logs, and implement resilient recovery mechanisms, ensuring builds remain deterministic and maintainable in distributed environments.

    Systematic Approach to Identifying and Resolving Build Failures

    Build failures often stem from predictable patterns, including dependency mismatches, syntax errors, or environment misconfigurations. A systematic approach involves categorizing failures by phase (e.g., dependency resolution, compilation, testing) and applying targeted diagnostics. The following steps ensure efficient root cause analysis:
    1. Phase Isolation
      Break down the build cycle into discrete stages (e.g., `fetch`, `build`, `test`) and isolate the failing phase using tool-specific flags. For example:
      mvn dependency:resolve -Dverbose=true (Maven)
      go mod tidy -v (Go)
      Logs from isolated phases reveal whether failures originate from external dependencies, toolchain issues, or source code.
    2. Dependency Validation
      Verify dependency integrity by cross-referencing:
      • Lock files (e.g., `package-lock.json`, `go.sum`) against resolved versions.
      • Network connectivity to repositories (e.g., `curl -v https://repo.maven.apache.org/maven2`).
      • Version conflicts using tools like:
        npm ls (Node.js)
        pip check (Python)
    3. Compiler and Toolchain Diagnostics
      Enable detailed logging for compilers and build tools:
      gcc -Wall -Wextra -v (GCC verbosity)
      rustc --verbose (Rust compiler flags)
      Focus on warnings (e.g., `-Werror` in GCC) and toolchain compatibility (e.g., Python `pyenv` versions).
    4. Environment Consistency Checks
      Document and enforce build environment variables (e.g., `JAVA_HOME`, `PATH`) using:
      env | grep -E 'JAVA|PATH|PYTHON' docker inspect --format='{{.HostConfig.Env}}'
      Containerized builds (e.g., Docker) should include health checks for critical services.
    5. Log Analysis Techniques
      Parse build logs for patterns using tools like:
      • grep -i "error\|fail\|warning" build.log (Linux/macOS)
      • Select-String -Pattern "error|fail" -Path build.log (PowerShell)
      • Structured logging frameworks (e.g., JSON logs with `jq` filtering):
        jq '. | select(.level == "ERROR")' build.json
      Prioritize logs with timestamps to correlate failures across distributed nodes.

    Checklist for Debugging Build Phase Timeouts or Hangs

    Timeouts or hangs often indicate resource exhaustion, deadlocks, or inefficient tool configurations. The following checklist provides actionable steps to diagnose and resolve such issues:
    1. Resource Contention Analysis
      Use system monitoring tools to identify bottlenecks:
      top -c -p $(pgrep -f 'javac\|gcc\|npm') (CPU/memory)
      iotop -o -p $(pgrep -f 'docker\|maven') (I/O)
      ss -tulnp | grep -E '3306|5432|8080' (network ports)
      Key metrics:
      • CPU: >90% usage for >5 minutes.
      • Memory: Swapping or OOM killer invocations.
      • Disk I/O: Latency >100ms (check iostat -x 1).
    2. Build Tool Diagnostics
      Enable tool-specific timeouts and profiling:
      mvn -T 4C -Dmaven.compiler.fork=true (Parallel builds with forked JVMs)
      npm config set maxsockets 10 (Limit concurrent requests)
      go build -race (Detect data races in Go)
    3. Dependency Fetch Timeouts
      Adjust timeouts for repository access:
      ~/.m2/settings.xml (Maven):
                  <settings>
      <mirrors>
      <mirror>
      <id>central</id>
      <url>https://repo.maven.apache.org/maven2</url>
      <mirrorOf>central</mirrorOf>
      <connectionTimeout>60000</connectionTimeout>
      </mirror>
      </mirrors>
      </settings>
    4. Network and Proxy Issues
      Verify connectivity to external services:
      curl -v --connect-timeout 10 https://registry.npmjs.org telnet github.com 443
      Use tcpdump or Wireshark to inspect packet loss.
    5. Build Cache Corruption
      Clear and regenerate caches:
      rm -rf ~/.npm/_cacache ~/.gradle/caches docker system prune -a (For Docker-based builds)
    6. Parallelism Limits
      Reduce concurrency if resource contention is detected:
      make -j1 (GNU Make)
      npm config set max-parallel 2

    Structured Template for Build Cycle Wheel Error Messages

    Standardized error messages improve debugging efficiency by providing actionable context. The following template includes placeholders for critical failure attributes:
    Field Description Example
    phase Build cycle phase where failure occurred (e.g., dependency-resolution, compilation). phase: "compilation"
    tool Build tool or compiler name (e.g., gcc, npm). tool: "gcc"
    exit_code Non-zero exit code returned by the tool. exit_code: 1
    error_message Raw error output from the tool. error_message: "fatal error: header file 'foo.h' not found"
    recommended_fixes List of potential solutions with severity (e.g., high, low).
    recommended_fixes: [
    {"action": "install_missing_header", "severity": "high"},
    {"action": "check_include_paths", "sever

    Visualization and Documentation of the Build Cycle Wheel in Software Development

    The build cycle wheel represents a cyclical workflow in software development where phases like compilation, testing, packaging, and deployment interact dynamically. Visualizing this cycle enhances clarity, aids debugging, and ensures alignment across teams. Effective documentation of the wheel—including phases, tools, dependencies, and pitfalls—serves as a single source of truth for maintaining reproducibility and troubleshooting. Below are structured approaches to visualize, document, and automate insights from the build cycle wheel.

    Text-Based ASCII Diagram of the Build Cycle Wheel

    A text-based ASCII diagram provides an immediate, accessible representation of the build cycle wheel, highlighting phases, transitions, and common pitfalls. Below is a labeled diagram with annotations for circular dependencies and phase-specific challenges.

    +---------------------+ +---------------------+ +---------------------+
    | | | | | |
    | Compilation |------>| Testing |------>| Packaging |
    | | | | | |
    +-----------+---------+ +-----------+---------+ +-----------+---------+
    | | |
    | | |
    v v v
    +---------------------+ +---------------------+ +---------------------+
    | | | | | |
    | Dependency |<------| Integration |<------| Deployment |
    | Resolution | | (CI/CD) | | |
    | | | | | |
    +-----------+---------+ +-----------+---------+ +-----------+---------+
    | | |
    | | |
    v v v
    +---------------------+ +---------------------+ +---------------------+
    | | | | | |
    | Version Control |------>| Feedback Loop |------>| Monitoring |
    | Sync | | (Logs/Metrics) | | & Rollback |
    | | | | | |
    +---------------------+ +---------------------+ +---------------------+

    Annotations for Common Pitfalls:

  • Circular Dependencies: Arrows between Dependency Resolution and Testing indicate risks of infinite loops if unresolved dependencies trigger recompilation.
  • Testing Bottlenecks: Delays in Testing (e.g., flaky tests) propagate to Packaging and Deployment, increasing cycle time.
  • Feedback Loop Gaps: Missing Feedback Loop data (e.g., skipped log analysis) reduces visibility into Monitoring failures.
  • Generating Interactive Build Cycle Wheel Visualizations

    Tools like Graphviz (DOT language) and Mermaid.js enable dynamic, interactive representations of the build cycle wheel. These visualizations can be embedded in documentation or dashboards, with hover-tooltips for phase details and clickable links to logs.

    Example: Mermaid.js Diagram for Build Cycle Wheel
    Mermaid.js supports flowchart syntax, making it ideal for collaborative environments (e.g., GitHub READMEs, Confluence). Below is a snippet for a build cycle wheel with annotations:

    flowchart TD
    A[Compilation] -->|Source Code| B[Testing]
    B -->|Test Results| C[Packaging]
    C -->|Artifact| D[Deployment]
    D -->|Logs/Metrics| E[Monitoring]
    E -->|Alerts| F[Feedback Loop]
    F -->|Requirements| A
    G[Dependency Resolution] -->|Libraries| A
    G -->|Build Tools| B
    H[Version Control] -->|Commits| A
    style A fill:#f9f,stroke:#333
    style B fill:#bbf,stroke:#333
    style C fill:#f96,stroke:#333
    style D fill:#6f9,stroke:#333
    style E fill:#9f6,stroke:#333
    click A "View Compiler Logs":::logLink
    click B "Run Test Suite":::testLink
    classDef logLink fill:#f9f,color:#000,stroke:#333,stroke-width:1px;
    classDef testLink fill:#bbf,color:#000,stroke:#333,stroke-width:1px;

    Key Features:

  • Color-Coded Phases: Highlights critical paths (e.g., Testing in blue, Deployment in teal).
  • Interactive Links: Clickable phases trigger actions (e.g., opening logs or test reports).
  • Annotations: Tooltips can describe pitfalls (e.g., "Circular dependency risk between Dependency Resolution and Testing").
  • Generating with Graphviz:
    Graphviz uses the DOT language for directed graphs. Below is an equivalent DOT snippet for the same wheel:

    digraph BuildCycle {
    rankdir=LR;
    node [shape=box, style=filled, fillcolor=lightgray];
    edge [fontname="Arial", fontsize=10];

    A [label="Compilation", fillcolor="#f9f"];
    B [label="Testing", fillcolor="#bbf"];
    C [label="Packaging", fillcolor="#f96"];
    D [label="Deployment", fillcolor="#6f9"];
    E [label="Monitoring", fillcolor="#9f6"];
    F [label="Feedback Loop", fillcolor="#f9f"];
    G [label="Dependency Resolution", fillcolor="#bbf"];
    H [label="Version Control", fillcolor="#f96"];

    A -> B [label="Source Code"];
    B -> C [label="Test Results"];
    C -> D [label="Artifact"];
    D -> E [label="Logs/Metrics"];
    E -> F [label="Alerts"];
    F -> A [label="Requirements"];
    G -> A [label="Libraries"];
    G -> B [label="Build Tools"];
    H -> A [label="Commits"];

    { rank=same; G H; }
    }

    Tools to Render:

  • Mermaid.js: Embed in Markdown (e.g., GitHub, VS Code) or use the Mermaid Live Editor.
  • Graphviz: Install via `apt-get install graphviz` (Linux) or use Graphviz Online.
  • Documentation Template for the Build Cycle Wheel

    A standardized Markdown table captures the build cycle wheel’s structure, tools, dependencies, and troubleshooting steps. Below is a template for project documentation:
    PhaseToolsDependenciesCommon PitfallsTroubleshooting
    CompilationGCC, Clang, MSVCSource Code, Header FilesSyntax Errors, Missing IncludesRun `make clean`; verify `#include` paths.
    TestingJest, pytest, JUnitCompiled Binaries, Test DataFlaky Tests, Timeout ErrorsIsolate failing tests; check network/timeouts.
    PackagingMaven, npm, DockerTested Artifacts, Config FilesVersion Mismatches, Corrupt ArchivesValidate checksums; rebuild with `--clean`.
    DeploymentKubernetes, Ansible, TerraformPackaged Artifacts, IAM PermissionsPermission Denied, Network LatencyAudit RBAC policies; use `kubectl describe`.
    MonitoringPrometheus, ELK Stack, DatadogLog Files, Metrics EndpointsMissing Metrics, Alert FatigueConfigure retention policies; use SLOs.
    Feedback LoopSlack, PagerDuty, JiraMonitoring Data, User ReportsUnactionable Alerts, Delayed FeedbackImplement tiered escalation; automate triage.
    Dependency Resolutionnpm, pip, Go ModulesPackage Manifests (e.g., `package.json`)Version Conflicts, Proxy IssuesUse `npm dedupe`; configure proxy settings.
    Version ControlGit, SVNBuild Scripts, Config FilesMerge Conflicts, Stale BranchesRebase frequently; use `git blame`.
    Annotations for the Template:
  • Tools Column: Lists primary tools with alternatives (e.g., `npm`/`yarn` for packaging).
  • Dependencies Column: Specifies inputs/outputs for each phase (e.g., Testing requires Compilation outputs).
  • Pitfalls Column: Highlights phase-specific risks (e.g., Deployment failures due to IAM misconfigurations).
  • Troubleshooting Column: Provides actionable steps with tool-specific commands.
  • Automated Build Cycle Wheel Execution Time Analysis

    Parsing build logs to

    A well-optimized build cycle wheel is not merely a sequence of commands but a strategic framework that balances speed, resource usage, and maintainability. By leveraging incremental builds, intelligent caching, and robust CI/CD integration, teams can reduce latency and minimize redundant efforts. The methodologies outlined here—from benchmarking tools to interactive visualizations—empower developers to design resilient build systems that adapt to evolving project demands. Mastery of the build cycle wheel ultimately translates to faster iterations, fewer deployment bottlenecks, and a more efficient development lifecycle.

    build cycle wheel - Kesimpulan

    build cycle wheel - Kesimpulan

    Leave a Comment

    Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of ir.msu.ac.zw.